AI

Announcing Gas City 1.0! April 28, 2026 Gas City AI

Announcing Gas City 1.0!

You may have heard from Steve Yegge, the creator of Beads and Gas Town, that we’ve released Gas City 1.0! As the CEO of the newly minted Gas City, Inc., I thought I’d provide some additional details on Steve’s excellent blog post.

Welcome to Gas City

It’s hard to look back on the release of ChatGPT as anything but the firing of a starter pistol. In that time, we’ve completely changed how software engineers do their jobs, moving from handwriting their code to using CLI coding agents like codex or claude to do the coding for them. Unfortunately the cost of the increased efficiency in producing the code is reduced quality in the output. It’s not uncommon for professional software engineers to declare the agent output to be “slop.”

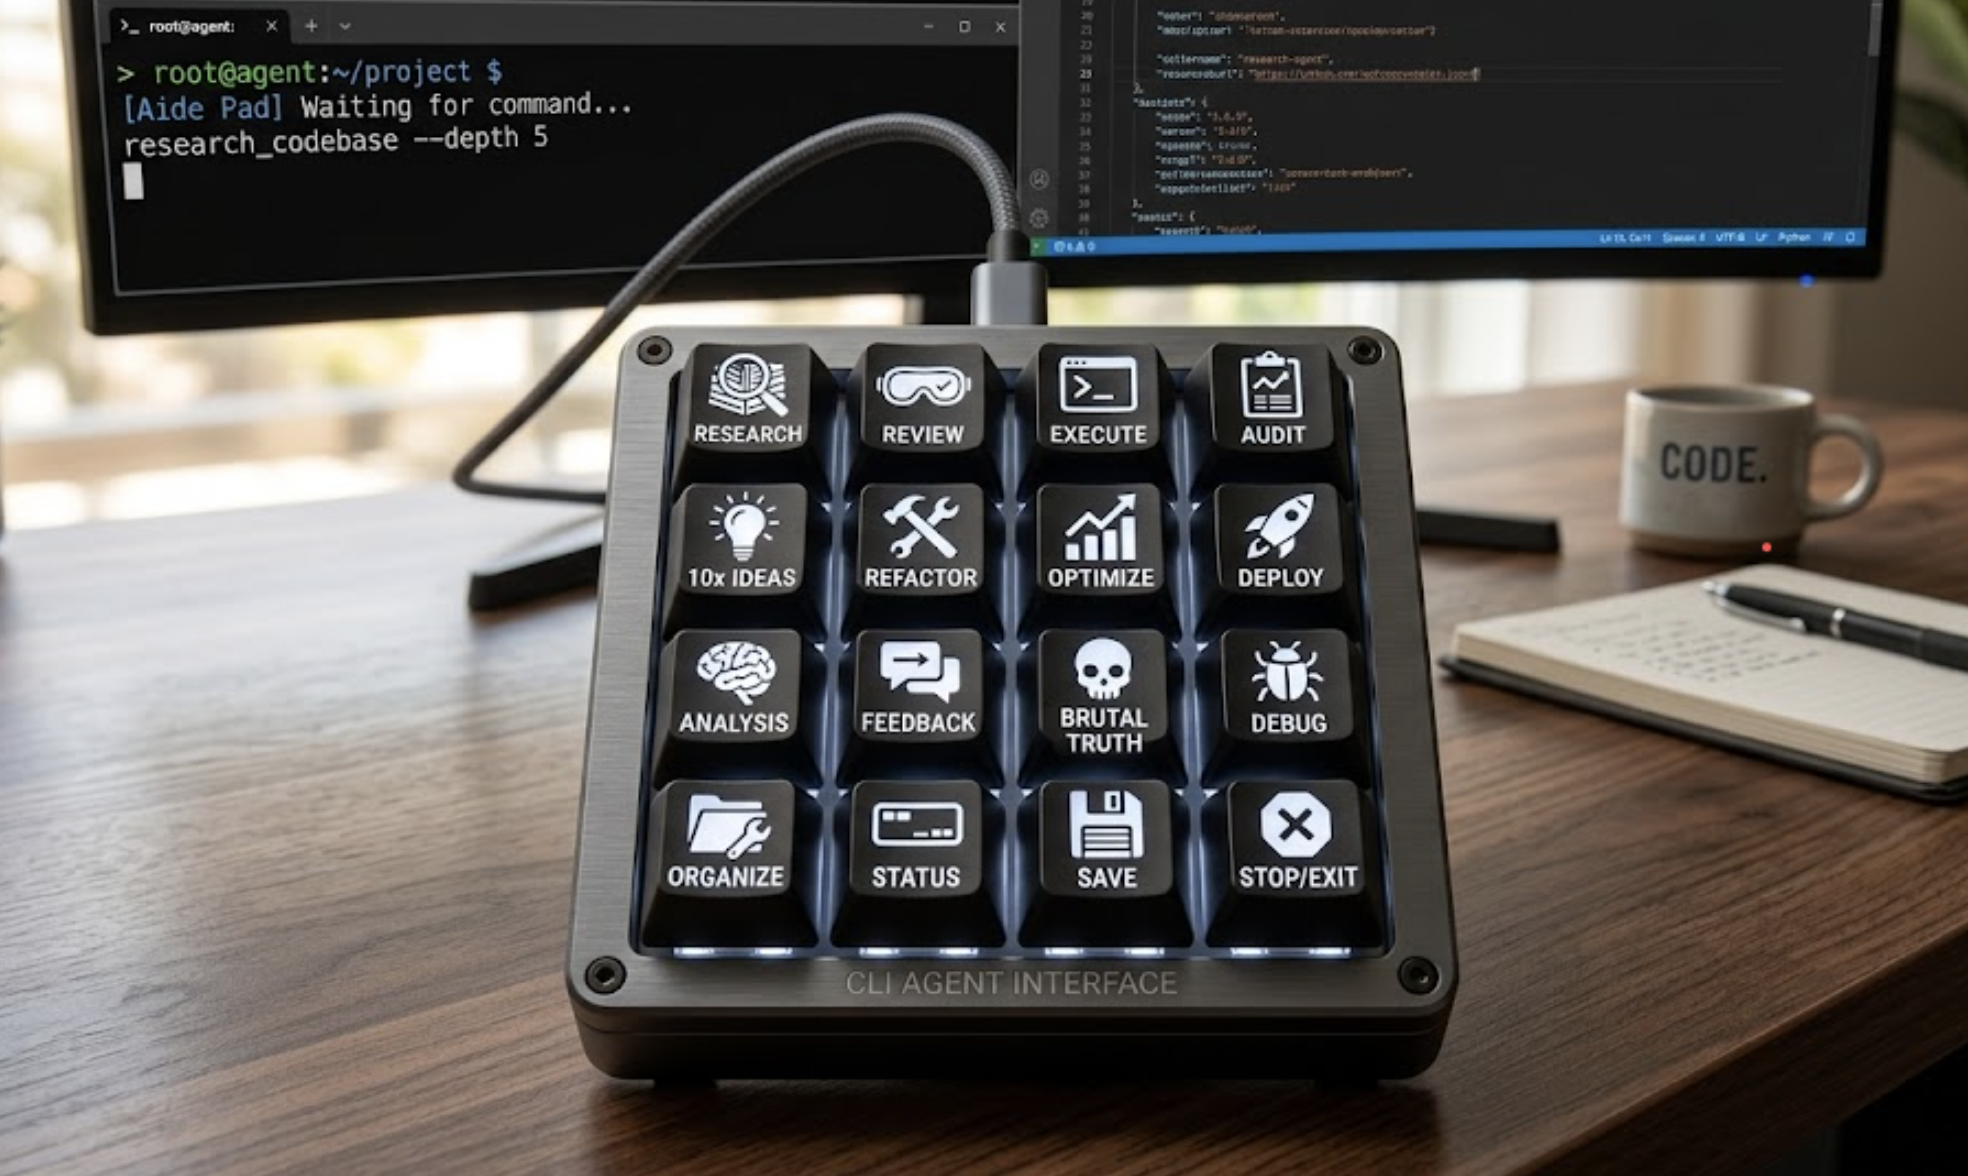
In an attempt to drive up the quality of agent output, the typical agentic engineering experience has turned into a babysitting job. You cycle between your terminals, reminding each coding agent what they’re supposed to be building, injecting quality guardrails periodically as those details fall out of their context, manually asking for sub-agents to do research deep dives or reviews. All of that is if you can track where each agent is on their quality path and what the right magic phrases are, based on a year of cave drawings and campfire stories. In fact, I even know of one prolific agentic engineer who has built themselves a custom keyboard so that all of their favorite prompts are available at the touch of a button.

If you’d rather move back to engineering, I recommend Gas City.

agents + orchestration = joy

Gas City is for agentic engineers to build their own software factories.

A software factory is a system for building, validating, deploying, operating, and maintaining production software.

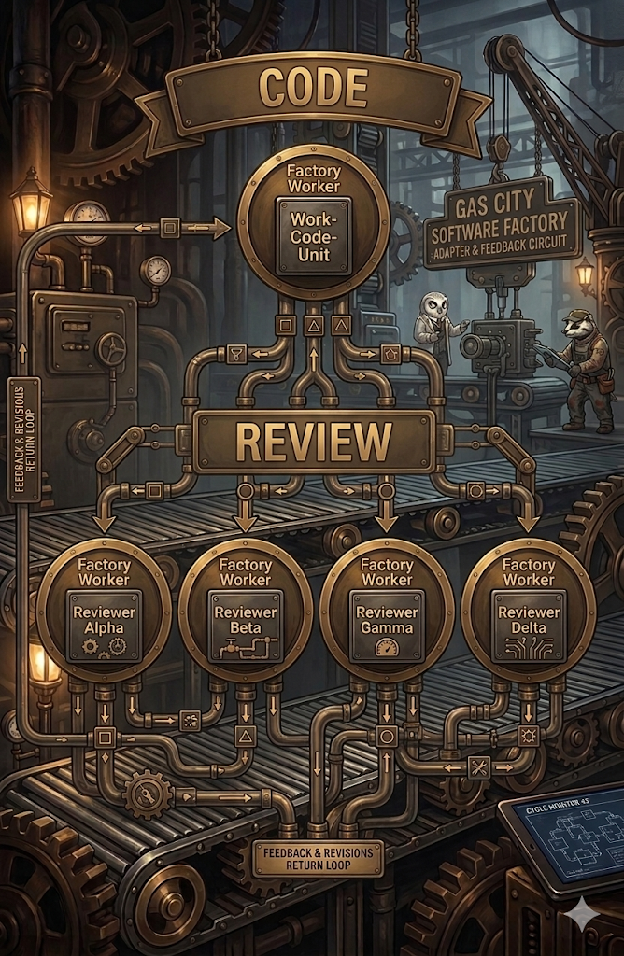
To enable all of this, the core of Gas City is an agentic orchestration engine. Its job is to let you harness swarms of agents to color inside the lines that you define. As an example, here’s a simple Gas City formula that iterates over code incorporating reviews from other agents:

# formulas/code-review-loop.toml
formula = "code-review-loop"
version = 2
contract = "graph.v2"

[[steps]]
title = "Code Review Loop"
id = "code-review-loop"

[steps.check]
title = "Code + Review (loop up to 3 times)"
max_attempts = 3

[steps.check.check]
mode = "exec"
title = "Check Review Results"
path = "checks/review-gate.sh" # reads reviews to decide whether to loop or not
  
[[steps.children]]
id = "code"
title = "Write code + tests"
description = "Write code and tests based on user input and agent feedback"
metadata = { "gc.run_target" = "coder" }

[[steps.children]]
id = "review-codex"
title = "Code Review (Codex)"
description = "Review the implementation for architectural best practices."
needs = ["code"]
metadata = { "gc.run_target" = "reviewer-codex" }

[[steps.children]]
id = "review-claude"
title = "Code Review (Claude)"
description = "Review the implementation for architectural best practices."
needs = ["code"]
metadata = { "gc.run_target" = "reviewer-claude" }

[[steps.children]]
id = "review-gemini"
title = "Code Review (Gemini)"
description = "Review the implementation for architectural best practices."
needs = ["code"]
metadata = { "gc.run_target" = "reviewer-gemini" }

[[steps.children]]
id = "synthesize-reviews"
title = "Synthesize review results"
description = """
  Read all three review outputs, produce one concise synthesis, and decide whether
  the implementation is approved.

  Write the synthesis to docs/reviews/latest.md.

  Close this bead with:
  - review.verdict=approved if no blocking or major findings remain
  - review.verdict=iterate if another coding pass is required
  - gc.outcome=pass
"""
needs = ["review-codex", "review-claude", "review-gemini"]
metadata = { "gc.run_target" = "synthesizer" }

Five agents are involved, one coder, three reviewers and one review synthesizer.

The reason to pull in multiple agents from multiple vendors is that each one has been trained differently and has a different point of view. It’s the combination of those points of view, as well as multiple iterations, that drives up the quality of your agentic output.

The agent definitions are separate for reuse amongst formulas, but they each look like this:

# agents/coder/agent.toml
scope = "rig"
wake_mode = "fresh"
provider = "codex"
option_defaults = { model = "gpt-5.5" }
default_sling_formula = "code-review-loop"

Each agent also has a prompt template file:

{{/* agents/coder/prompt.template.md */}}
# Coder
## Role
You implement code changes. Read the request, any prior review feedback,
and the project context, then write the implementation with tests and commit it.

## Inputs
- The current routed formula step.
- Project context: AGENTS.md, specs/ and docs/
- Prior review feedback in docs/reviews/ (if retrying after a failed review cycle).

## Graph Work Process
1. Run `gc prime`.
2. Read the routed step and project files.
3. If docs/reviews/ contains prior feedback, read it and address findings.
4. Implement the change with tests.
5. Commit to a feature branch.
6. Close the current step.

## Output Format
A git commit on a feature branch with passing tests.

## Close Behavior                                       
Close the current step when the commit is made and tests pass.

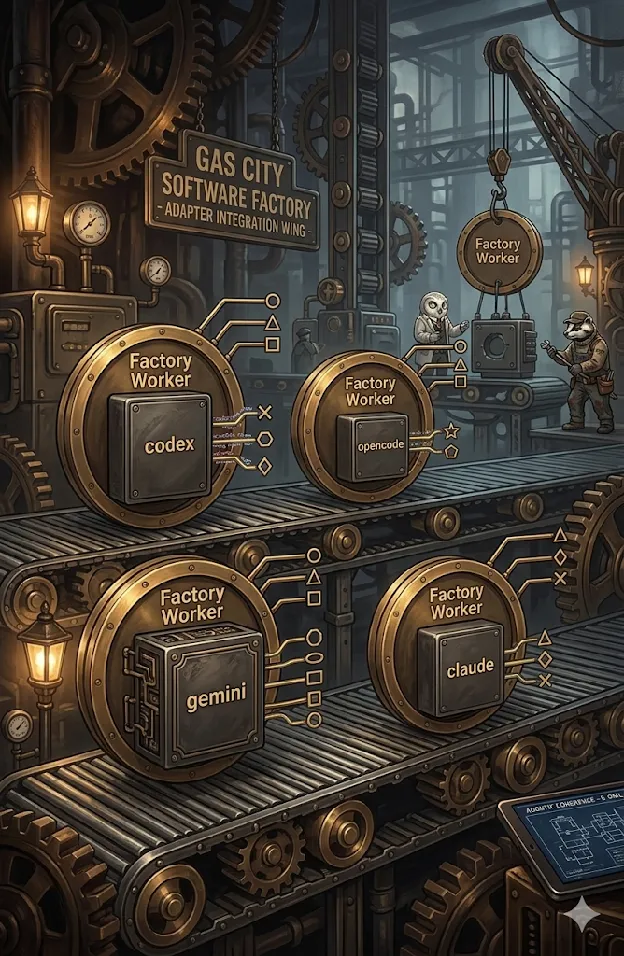
Notice that the definition only has to mention “codex” and not set up a path or CLI args or output formats. That’s because Gas City has a built-in “factory worker” protocol to standardize access to your favorite CLI coding agents, including codex, claude, and gemini, of course, but also amp, opencode, pi, etc. That means that you can change your coder agent to be another OpenAI model or another CLI coding agent altogether, all with a simple set of declarative settings and without changing your formulas. And the settings also support MCP servers, skills, overlays, and the full set of capabilities that you need for your agents, all in an agent-neutral way.

Formulas — step-by-step workflows for as many agents from as many providers as you like — are the key to moving from babysitting your agents to harnessing them. To be able to handle our record peak of 74 PRs in a single day, Gas City runs on Gas City. For a more in-depth look at the power of agentic orchestration, I recommend Orchestration Is All You Need.

get involved!

Harnessing agents with formulas is the core of Gas City, but there’s more, including beads (the way work is defined), orders (trigger-based automations), packs (shareable sets of agents, formulas and orders), a rich event stream, and the list goes on!

To help you get up to speed on all of this tech, I recommend the Gas City docs, made explicitly friendly for you AND your agents. Also, there’s a vibrant and growing community of people experimenting with Gas City and working together to invent the future of software engineering, with 2600+ members in the Gas Town Hall Discord server. From this community, the core projects — Beads, Gas Town, and Gas City in the Gas Town Hall organization on GitHub — have gathered more than 35K stars, with more than 5,000 PRs and 2,500 issues from 500+ contributors.

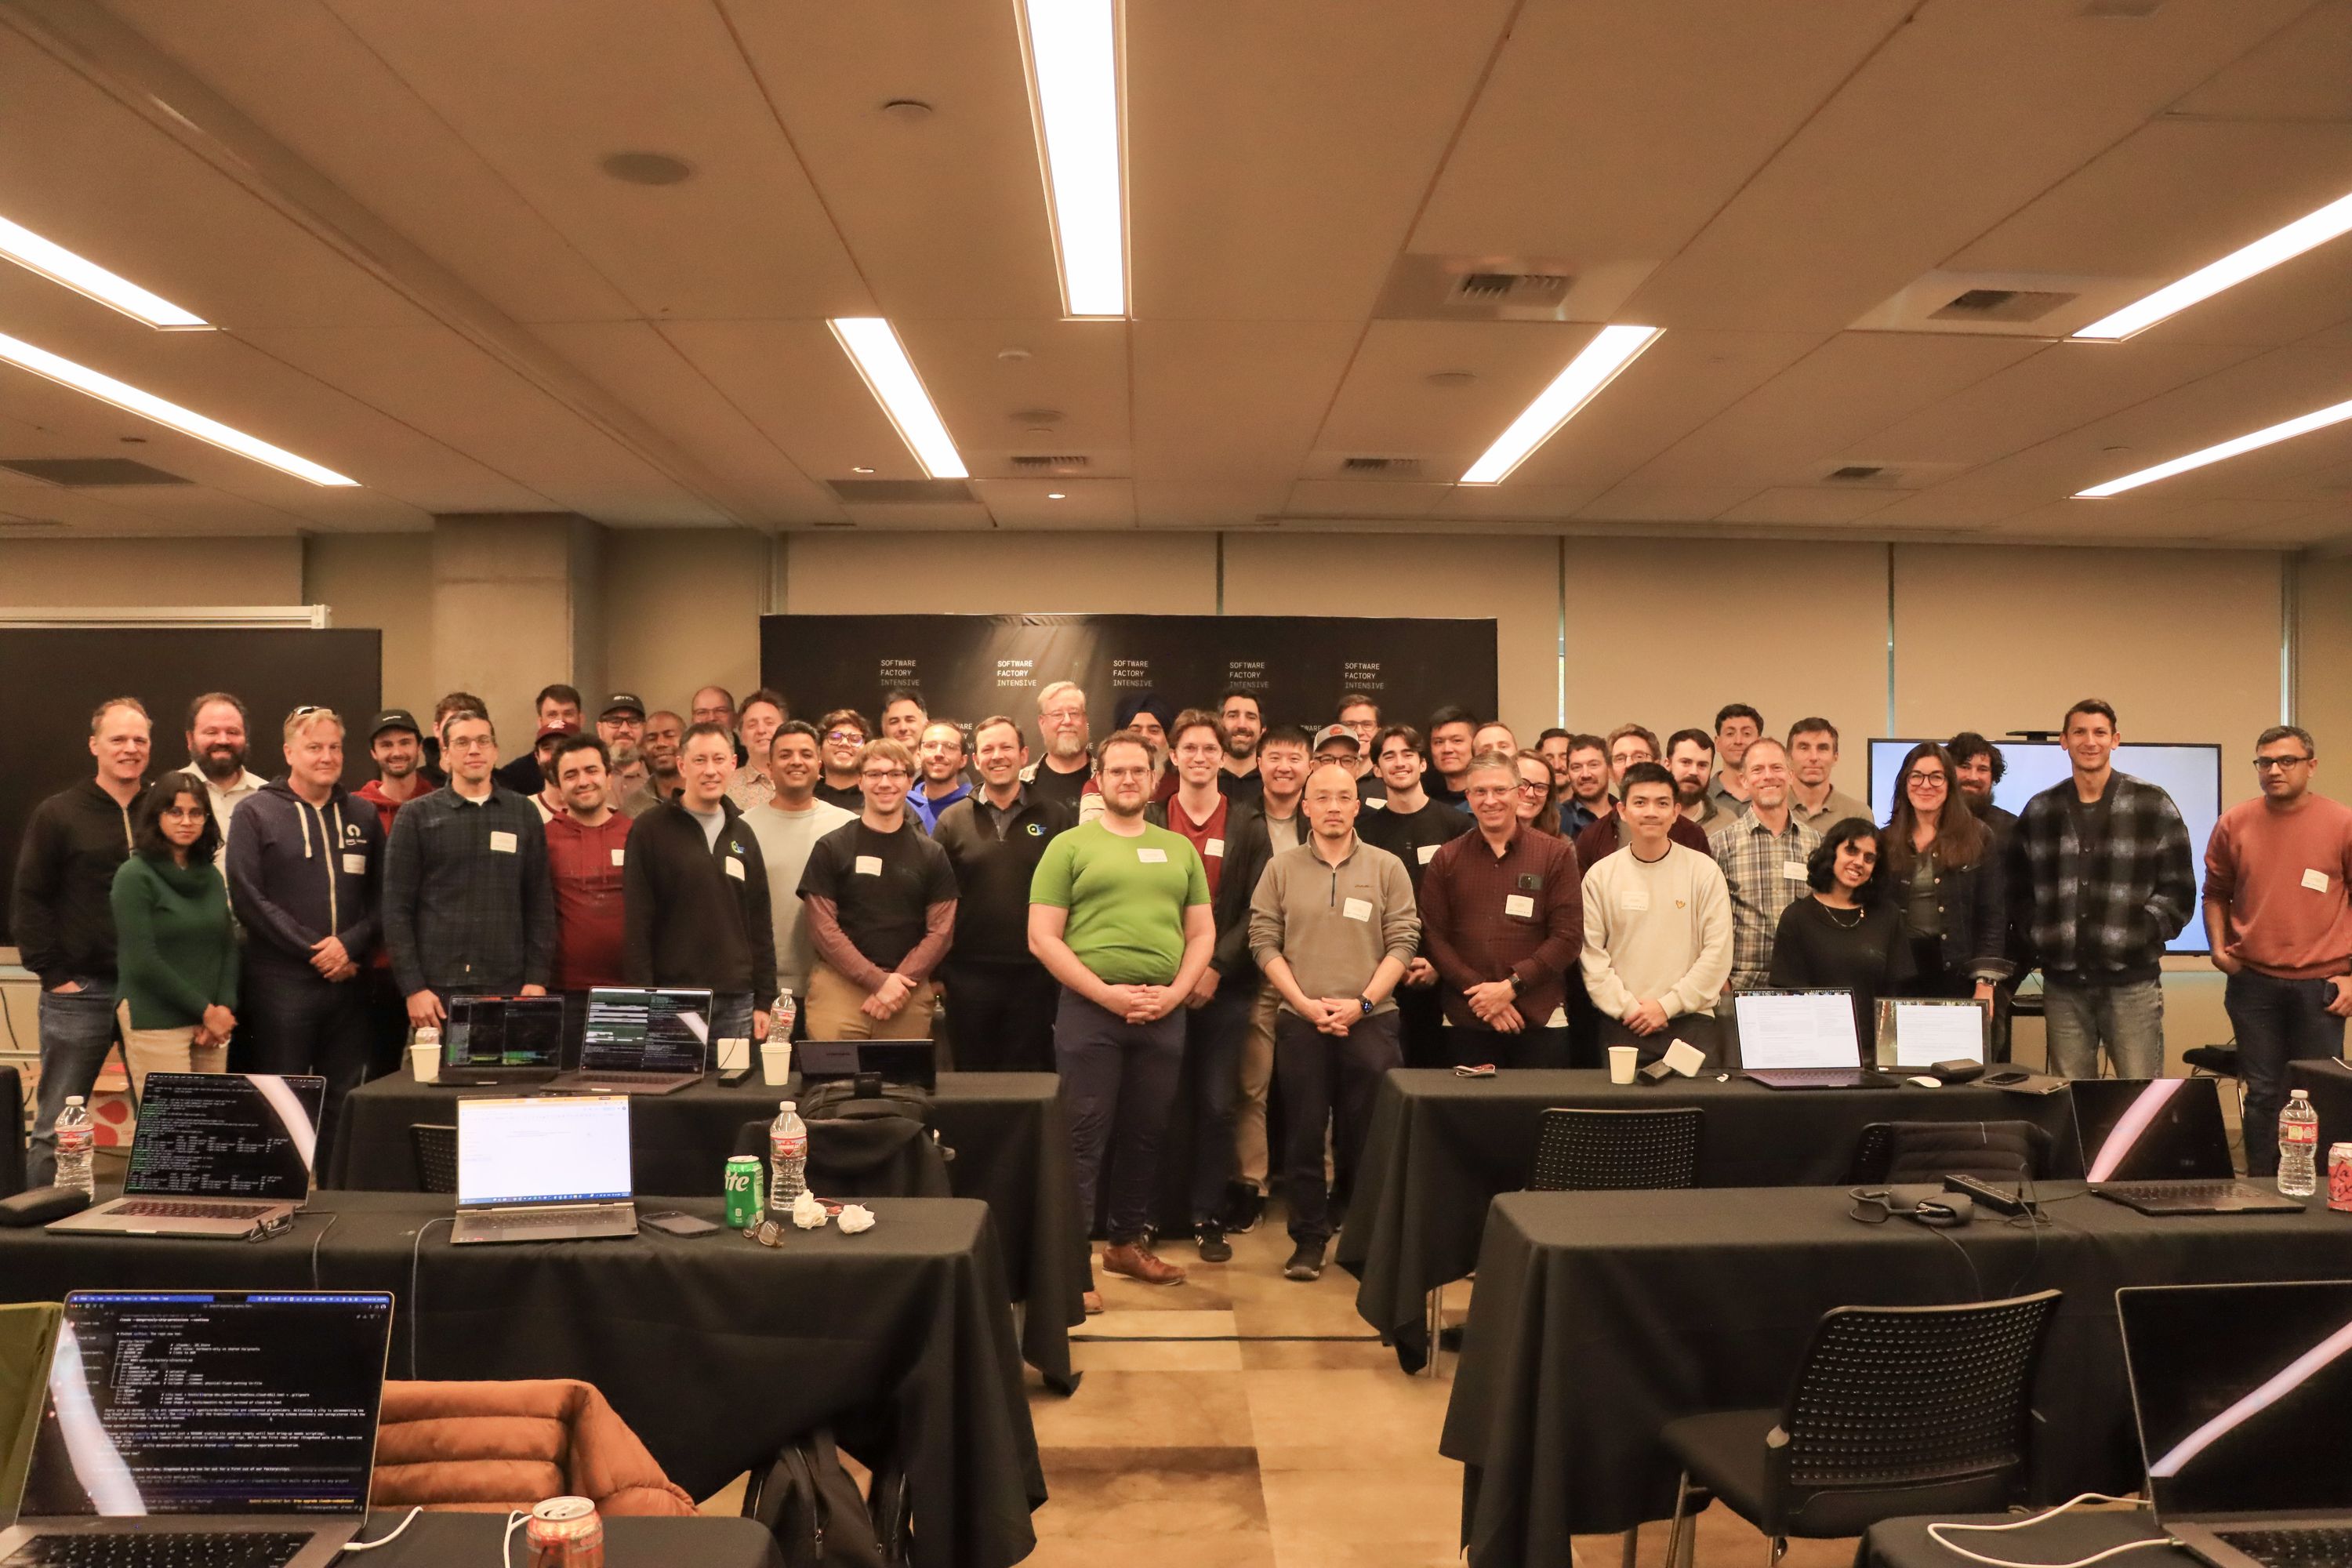
But that’s not all, the popularity of Gas City has grown enough that Actual AI has started a set of hands-on workshops called The Software Factory Intensive, with five cities already planned. In fact, last week was the first one and we had more than 70 engineers building their own software factories with Gas City.

swi-seattle-group

Things are moving fast: from Steve’s initial commit on Beads in October to hands-on workshops across multiple cities running right now.

Interested in joining us? Come on over to Gas City Hall — we’re happy to have you!

where are we?

You can build your own custom agent keyboard if you want to.

coding-agent-keyboard

If you’d like to take the leap to agentic engineering instead, I recommend Gas City.

Orchestration Is All You Need April 21, 2026 Gas City AI

Orchestration Is All You Need

What agentic engineering looks like when you really mean it.

In the last year, as our AI software engineering tools have evolved, so have our software engineering processes. We have learned to take advantage of the tools to cut down the latency of our SDLC and CI/CD processes. We’ve already learned that if we’re not careful, we’re going to vibe code AI “slop,” the unchecked code and configuration that an AI coding agent generates when run without guardrails.

The kind of guardrails I mean come straight out of the software engineering 101 playbook:

  • Getting feedback from multiple points of view
  • Checking technical designs for completeness, consistency and accuracy
  • Comprehensive unit, UI, integration, performance and security test suites
  • Thorough error instrumentation and run-time monitoring in operation
  • Human taste and judgment as the definition of “done”

Using agents for what they’re good at (coding, checking, testing, iterating) while letting the humans set the bar for quality elevates your process from “it works on my machine” and defines the “agentic engineering” discipline. You can use agents interactively to get the quality you’re looking for, if you’re careful to apply the guardrails. But if you want to build automated pipelines that require less and less human interaction over time, you’re going to have to start with something called harness engineering.

“Harness engineering” is the act of gathering together the underlying LLM with the tools and context (data, instructions, information about the environment) into a program optimized for a specific task. Each one of the CLI coding agents itself is a harness that’s optimized for getting the most out of the underlying LLM from a latency, throughput and quality point of view, packaged in a TUI with programmatic access built in.

And while it’s easy enough for a human to switch between tools from an interactive point of view, it’s real work to be able to switch between codex and opencode in your automated processes. While each of them provides the programmatical surface area you need to automate them, all agents are different in their invocation arguments, service endpoints, etc. To solve that problem, we need harness engineering again, but one level of abstraction up.

As an example, the Gas City OSS project defines a provider protocol that we implement on top of each of the major (and several of the long tail) CLI coding agents to enable them to be swapped in and out of city, pack and formula definitions (more on that later):

// Pseudo-code for the canonical in-memory worker API.
type FactoryWorker interface {
    // Lifecycle
    Start(context.Context) error
    StartResolved(context.Context, string, runtime.Config) error
    Attach(context.Context) error
    Create(context.Context, CreateMode) (sessionpkg.Info, error)
    Reset(context.Context) error
    Stop(context.Context) error
    Kill(context.Context) error
    Close(context.Context) error
    Rename(context.Context, string) error
    State(context.Context) (State, error)

    // Messaging
    Message(context.Context, MessageRequest) (MessageResult, error)
    Interrupt(context.Context, InterruptRequest) error
    Nudge(context.Context, NudgeRequest) (NudgeResult, error)

    // Transcript and History
    History(context.Context, HistoryRequest) (*HistorySnapshot, error)
    Transcript(context.Context, TranscriptRequest) (*TranscriptResult, error)
    TranscriptPath(context.Context) (string, error)
    AgentMappings(context.Context) ([]AgentMapping, error)
    AgentTranscript(context.Context, string) (*AgentTranscriptResult, error)

    // ... and more!
}

Not only does this allow you to eliminate the programmatic differences that get in the way of your swapping yesterday’s best coding agent out for today’s best agent out of your automations, but it also allows you to easily take advantage of the variations between the models, e.g. cost, limits, quality, availability, suitability to a specific job (e.g. planning, coding, image processing).

The use of the provider harness in Gas City allows you to turn a CLI coding agent into a “factory worker” that you can tailor to the specific job (“you’re an expert UX designer…”) and drop into your custom workflows (“write the plan, then get it reviewed by these other agents, then ask the UX designer agent to flesh out the jobs to be done, …”) that we call orchestrations.

orchestration all the way down

Reminding ourselves of human software engineering teams again, we have a series of workflows that human teams go through to get a product or feature out the door. For example, imagine an engineer that’s just written some code. Do they immediately release it to customers? No. They must solicit review feedback from their teammates first, dealing with any issues that arise. Only when they get the thumbs up are they allowed to merge new code into the main product codebase.

Now, if Eddie the Engineer is a human, he can do his coding, solicit feedback and iterate all on his own. Likewise, his teammates will get their notifications and do their part to keep the flow of software moving.

However, if Eddie is an AI coding agent, to do his part requires that he’s “orchestrated,” e.g. that he’s been defined as an expert software engineer running on the codex provider using the GPT5.4 model. Once an agent is included in an orchestration, we can have as many instances of it as we want, each dedicated to execution on its own work item with its own agent Eddie instance.

Once each Eddie is done with his work, the orchestration engine will hand it off to as many LLMs as you decide to review the work, gathering that feedback to iterate on until Eddie’s code gets a clean bill of health.

This isn’t theoretical. The code review orchestration we use with Gas City combines a dynamic set of agents configured to focus on security, performance, React, etc. that are then spread across the codex, gemini and claude providers so that we get a wide range of review feedback to iterate on. We know from experience that this greatly improves the quality of our code (and plans and tests and …).

Every part of our human software engineering processes can be turned into an agentic orchestration. The artifact-review-iterate process is the same for engineers, PMs, UX designers, etc. And those processes string together into the overall software process itself.

The factory worker harnesses allow you to bring the CLI coding agents into your orchestrations, but it’s the orchestrations that allow you to spread the work across as many agents as you can spin up.

embracing the bitter lesson

There’s a tempting alternative to all of this: just wait for the models to get good enough that you don’t need orchestrations. Eventually, the thinking goes, GPT-7 or Claude 6 or Gemini Ultra will be capable enough that you can hand it your repo and your customer feedback and walk away.

This is the wrong side of the bitter lesson. Rich Sutton’s observation was that general methods that leverage compute have always eventually beaten methods that leverage human-encoded domain knowledge. Waiting for the perfect model is turning away from that lesson. It’s a bet that compute will eventually stop mattering, that there’s a model capability threshold past which the apparatus becomes unnecessary. And while the singularity is by definition the horizon beyond which we cannot predict the future, the past is pretty clear about the benefits of being on the right side of that lesson.

A software factory is on the right side. Orchestrations are how you turn more compute into better output, indefinitely. Five agents from different providers providing feedback is how you broaden your range of feedback no matter how good any specific agent’s response is. A better model just makes the orchestration better.

And now let’s talk about how you might build the software factory to run your orchestrations.

Gas City: build your software factory

Like Steve Yegge’s Gas Town that inspired it, Gas City provides the harness that turns CLI coding agents from different vendors into factory workers that can be plugged into “formulas” (orchestrations) to execute “beads” (work) against multiple “rigs” (projects).

Another name for an agentic orchestration system is a “software factory” or “dark factory” (so named because you don’t need humans to run it). Gas City provides the pieces — the agentic harness, the orchestration engine, the automation engine — and lets you configure the software factory to match the way that you want to work.

Want to start from scratch to build your factory alongside your software? You can. Want to have a fully featured Gas Town out of the box? Gas City provides that as a pre-packaged “pack” that you can choose at initialization time. Want to define your own pack that defines your favorite combo of agents, formulas (orchestrations) and orders (automatically triggered scripts or formulas) and share it with a team? That’s exactly what packs are for.

In fact, we’ve engineered Gas City such that any orchestration system you can think of — Ralph Loops, StrongDM Software Factories, Anthropic Agent Teams — can be captured in a pack. We’ve already started to gather some of them in the gascity-packs repo with more to come.

Those packs come from our own use of Gas City to build Gas City, as you might expect. On a single day, we were able to merge 74 PRs. Of course, the only way we can handle that kind of volume is by using Gas City itself.

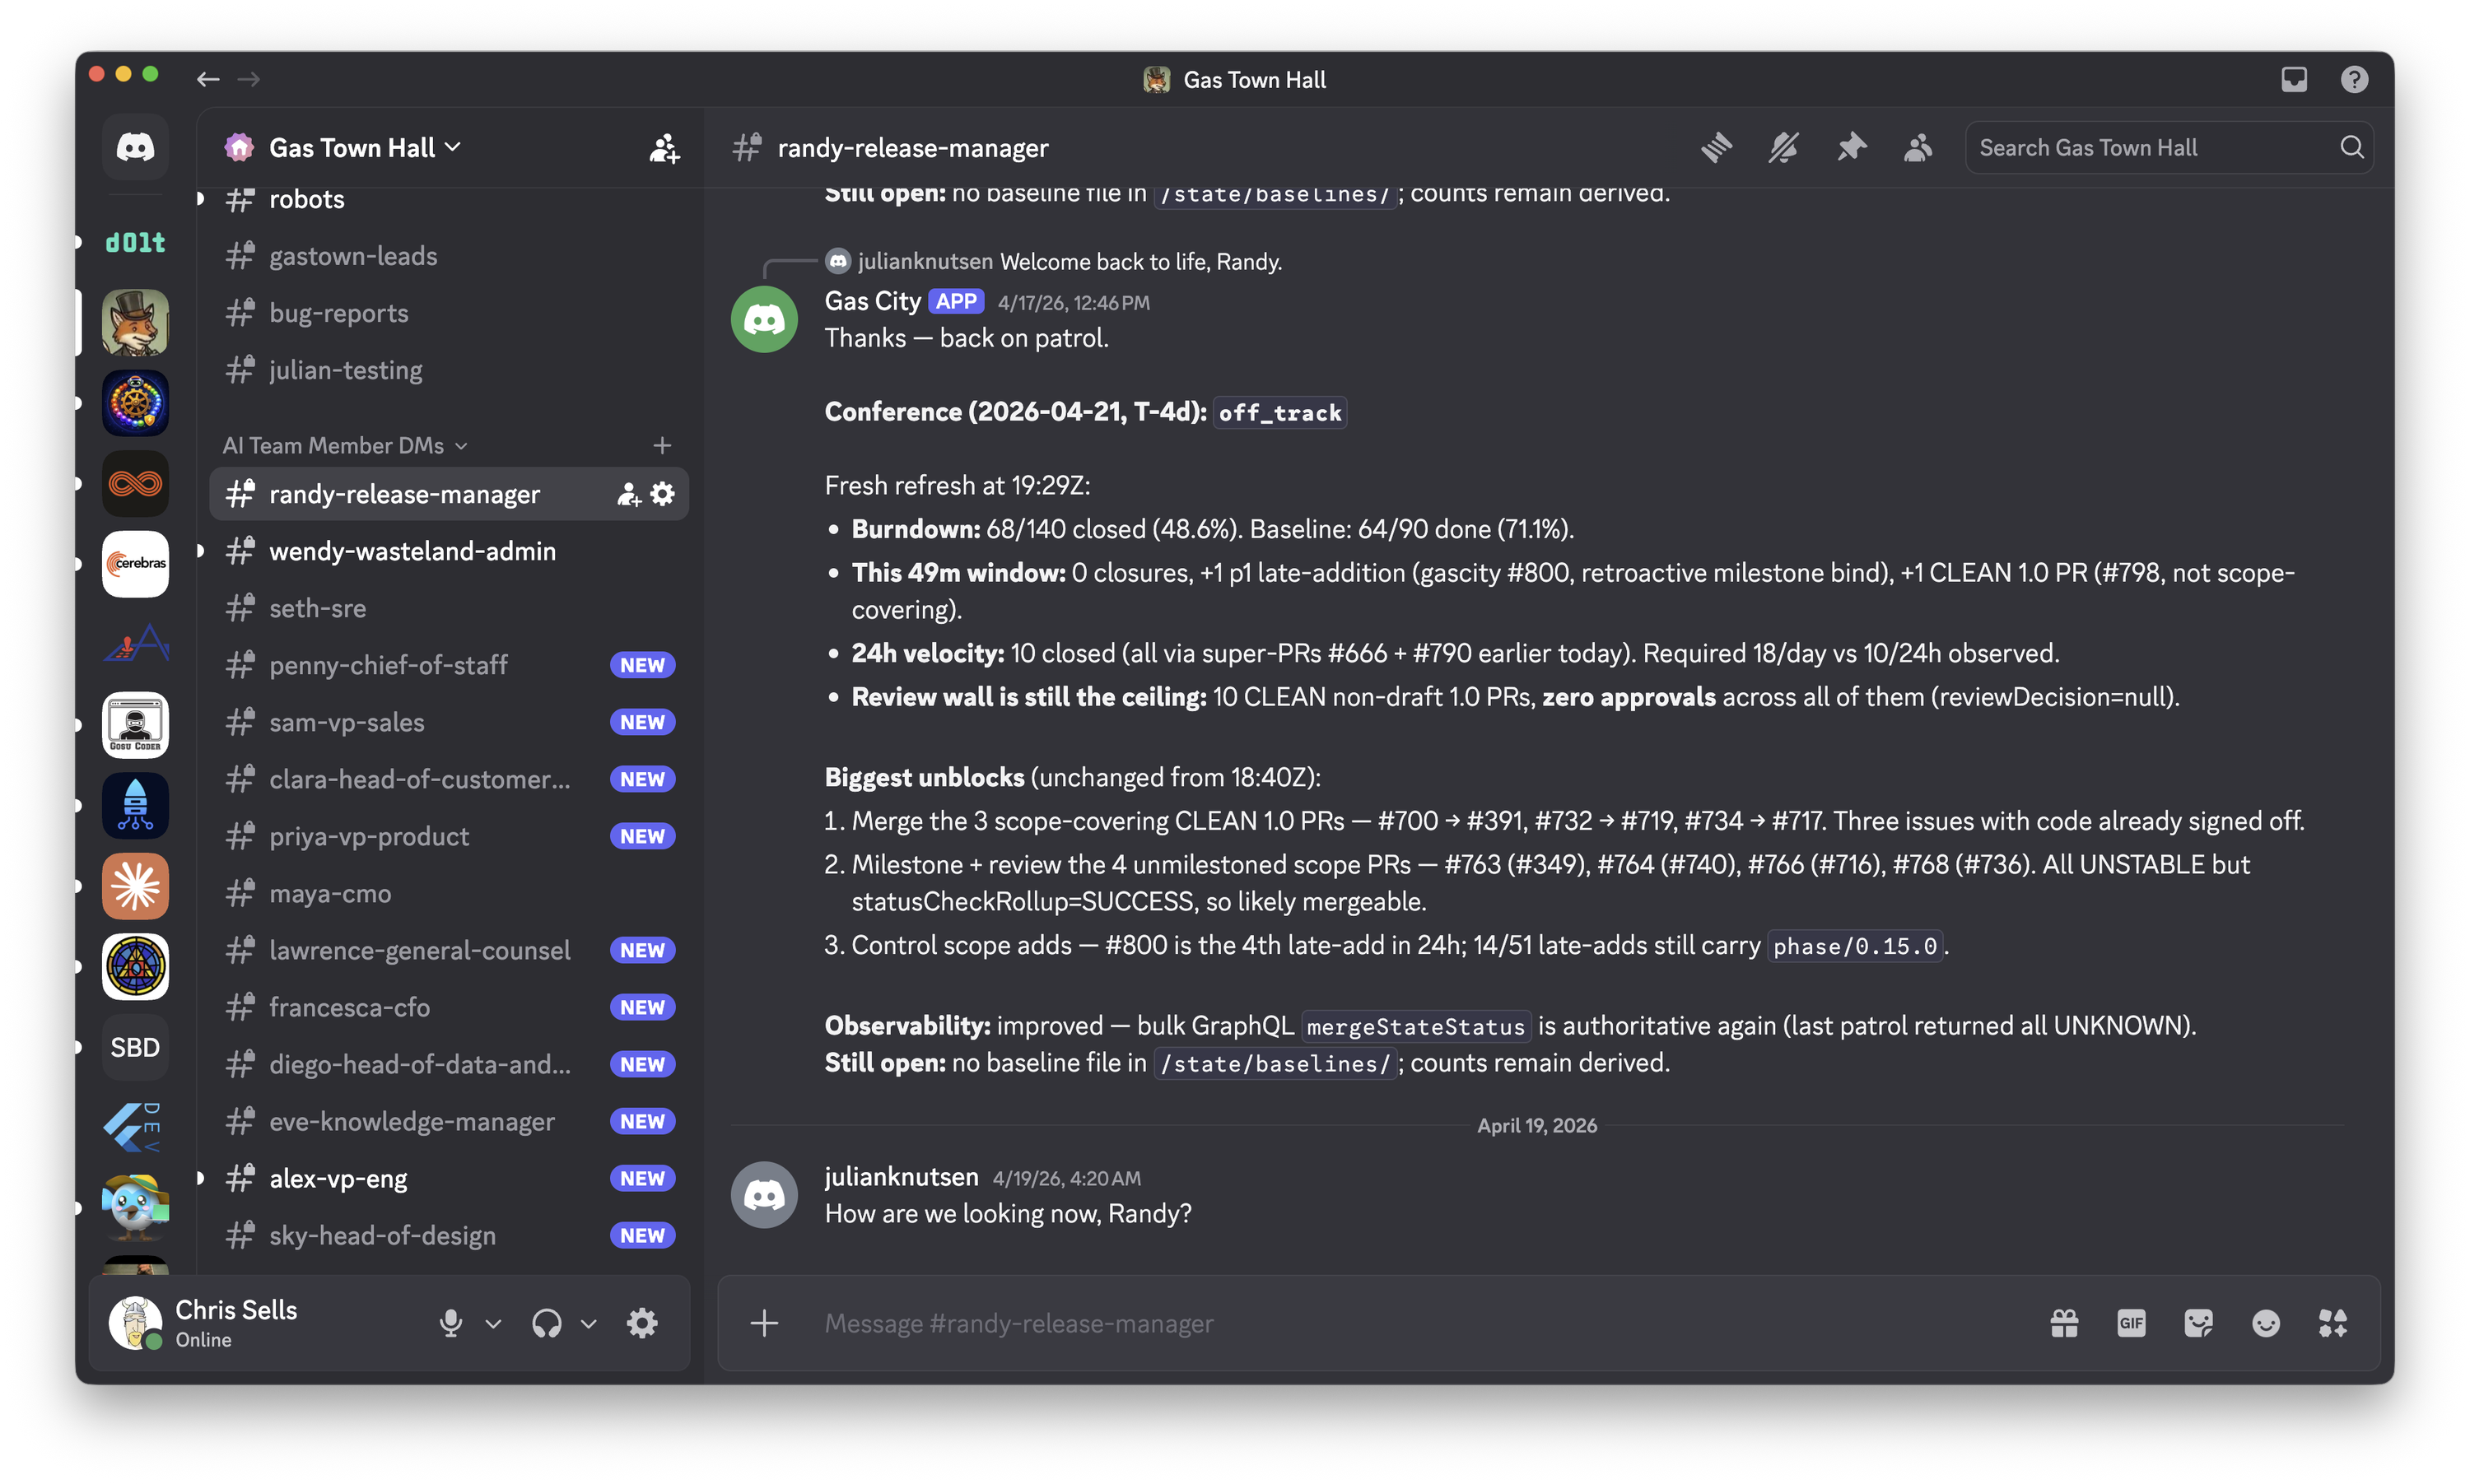
But what surprised us wasn’t just that we are using Gas City for implementation tasks. We’ve also built issue triage, deployment and operations. We’ve hired 15 agentic employees to help us run Gas City, Inc, ranging from marketing to release management. And, leaning on the techniques in OpenClaw, each of them has a personality and the ability to chat with us via Discord.

What we’re finding is that not only does Gas City evolve based on bug reports and feature requests, but the Gas City software factory itself evolves to meet the needs of the software. The more we push on the limits of what orchestrated agents can do, the more we realize that we’re just getting started!

getting involved

The Gas Town ecosystem has grown quite a bit in popularity since Steve Yegge submitted the first commit to the Beads project in October. Together, Beads, Gas Town and Gas City have gathered more than 35,000 stars, 5000 PRs and 2500 issues from more than 500 contributors.

In addition, we’ve got The Wasteland, which is our burgeoning set of federated Gas Towns and Cities for centralized management of distributed work. And we’ve got a hosted version of Gas City coming soon.

Of course, we’ve also got Gas City Hall, the community for all things in Gaslandia, including the Discord server, the social news feed, the docs and a link to the repo. Or perhaps you’d like some hands-on training? Then sign up for Software Factory Intensive, a two-day workshop from our partners at Actual.ai on how to build your very own software factory with Gas City.

where are we

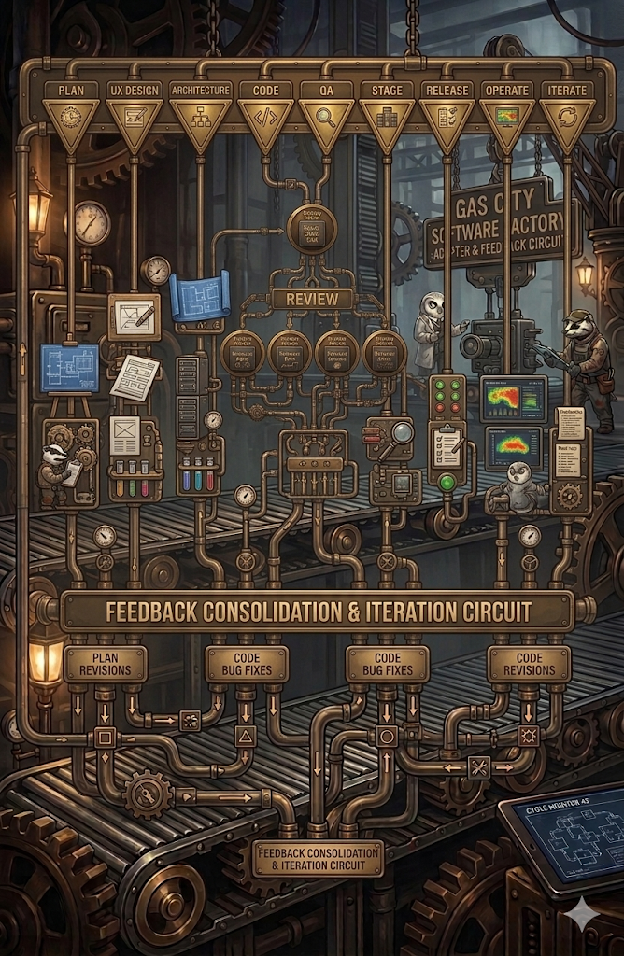
It might not have sunk in yet, but your job has changed. Instead of building the software, you’re going to be building the factory that builds the software. And reviews it. And validates it. And deploys and operates and maintains it.

But the agents still need you to define what “done” looks like. Encode those definitions into reusable orchestrations, spinning up as many as you need, and let the factory carry the work your team used to carry by hand.

Start with Gas City. Plug in the Gas Town pack or build your own from scratch. The ecosystem is open source, the community is growing, and we’re using it ourselves every day to build the thing you’re about to install.

Go build your factory.

Dartantic 2.0: The Nano Banana Edition December 10, 2025 Flutter AI

Dartantic 2.0: The Nano Banana Edition

tl;dr: If you’re new to dartantic, it’s a multi-provider agentic toolkit for Dart and Flutter developers that runs wherever Dart runs, i.e. Flutter web, desktop and mobile, CLI and server-side. Today there’s a new release, but you can skip all of that and head to the docs to get all you need to get started: https://docs.dartantic.ai.

Welcome to Dartantic 2.0!

Are you a Dart or Flutter developer deep into AI looking for a multi-provider agentic framework runs wherever Dart runs? Or perhaps you’re simply AI curious?

In either case, have I got a deal for you: today is the day that dartantic_ai 2.0 ships!

This is a big one. 12K+ lines of new and updated code. Unified thinking mode. Server-side tooling across all of the Big 3 providers: Google, Anthropic and OpenAI. New media generation models to create images and files of all kinds. Plus a ton of quality of life improvements. As well as some breaking changes (making omlets and all that).

And, of course, Nano Banana and Gemini 3 Pro Preview support.

What more could any young Dart or Flutter developer ask for? And I’ve got it all here for you right now.

Getting Started

If you’re new to Dartantic, here’s the 30-second version:

import 'package:dartantic_ai/dartantic_ai.dart';

void main() async {
  // Create an agent - use the default model or specify one
  final agent = Agent('google:gemini-3-pro-preview');

  // Send a message
  final result = await agent.send('Hello! What can you help me with?');
  print(result.output);
}

That’s it. Set your API key in the environment (OPENAI_API_KEY, GOOGLE_API_KEY, etc.) and you’re off. Want to switch providers? Change google to anthropic or openai-responses. Want a different model? Just change the model part of the string. For the full details, you’ve got the dartantic docs.

Unified Thinking API

Extended thinking (chain-of-thought reasoning) is now a first-class feature in Dartantic with a simplified, unified API across all providers.

Here’s what it looks like:

// Enable thinking
final agent = Agent('google:gemini-3-pro-preview', enableThinking: true);

// Access thinking as a first-class field
final result = await agent.send('Complex question...');
if( result.thinking != null) print(result.thinking);

This new model works the same for whatever provider you’re using (assuming they support thinking). The provider-specific fine-tuning options remain for advanced use cases:

  • GoogleChatModelOptions.thinkingBudgetTokens
  • AnthropicChatOptions.thinkingBudgetTokens
  • OpenAIResponsesChatModelOptions.reasoningSummary

But for most of us? Just flip the boolean and go.

Server-Side Tools Across Providers

Server-side tools are now supported across multiple providers. These are tools that run on the provider’s infrastructure, not yours.

Provider Tools Available
OpenAI Responses Web Search, File Search, Image Generation, Code Interpreter
Google Google Search (Grounding), Code Execution
Anthropic Web Search, Web Fetch, Code Interpreter

Here’s how you use them:

// Google server-side google search
final agent = Agent(
  'google',
  chatModelOptions: const GoogleChatModelOptions(
    serverSideTools: {GoogleServerSideTool.googleSearch},
  ),
);

// Anthropic server-side web search
final agent = Agent(
  'anthropic',
  chatModelOptions: const AnthropicChatOptions(
    serverSideTools: {AnthropicServerSideTool.webSearch},
  ),
);

// OpenAi server-side web search
final agent = Agent(
  'openai-responses',
  chatModelOptions: const OpenAIResponsesChatModelOptions(
    serverSideTools: {OpenAIServerSideTool.webSearch},
  ),
);

The pattern is consistent across providers even though the underlying implementations are completely different. That’s the whole point of dartantic. I hate to say “write once, run on any provider” but…

I’m also keeping my eye on Google’s file search tool which would bring Google to feature parity with OpenAI’s vector search capabilities. As soon as that lands in the Dart SDK, dartantic will support it.

Media Generation with Nano Banana Pro

If you’re into LLMs at all, you’ve probably seen talk about Nano Banana and Nano Banana Pro. The new Gemini media generation model supports both:

// Google provider uses Nano Banana by default (gemini-2.5-flash-image)
// for image generation
final agent = Agent('google');

final imageResult = await agent.generateMedia(
  'Create a b&w drawing of a robot mascot for a developer conference.',
  mimeTypes: const ['image/png'],
);

// Configuring the Google provider with Nano Banana Pro (gemini-3-pro-image-preview)
final agent = Agent('google?media=gemini-3-pro-image-preview');

final imageResult = await agent.generateMedia(
  'Create a 3D robot mascot for a developer conference.',
  mimeTypes: const ['image/png'],
);

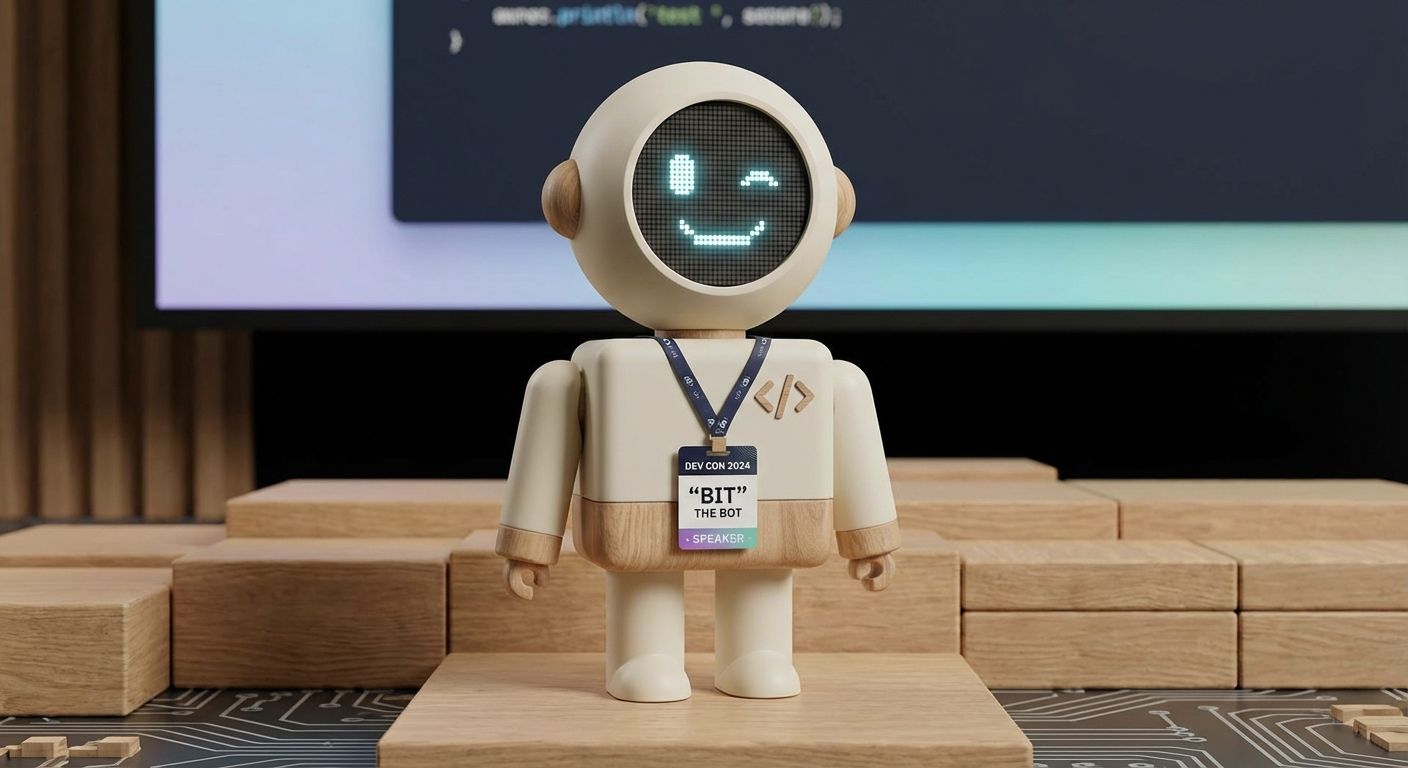
The image at the top of this blog post was generated by Nano Banana Pro during one of the test runs.

But here’s where it gets interesting. The dartantic’s media generation isn’t limited to images:

final agent = Agent('google');

// PDF generation - uses Gemini 3 Pro Preview + code execution
final pdfResult = await agent.generateMedia(
  'Create a one-page PDF with the title "Project Status" and '
  'three bullet points summarizing a software project.',
  mimeTypes: const ['application/pdf'],
);

// CSV generation - uses Gemini 3 Pro Preview + code execution
final csvResult = await agent.generateMedia(
  'Create a CSV file with columns: date, users, revenue. '
  'Add 5 rows of sample data.',
  mimeTypes: const ['text/csv'],
);

The media generation models (Google, Anthropic and OpenAI via the responses API) are implemented to route to their image generation if they have one and to their code execution environment if they don’t. For you, pick your provider, send in the prompt + mime type and you’re good to go.

Filling the Gaps

As I build out dartantic, I get to find out each provider’s “special” behavior.

Structured Output + Tools: For example, all of the Big 3 support tool calling and structured output. However, only OpenAI (via either the completions or responses APIs) supports tool calling AND structured output in the same request. Neither Google nor Anthropic do. So, inspired by the community (thanks @fatherOfLegends!), I’ve worked around that problem for both the Google and Anthropic providers so you can just do this and good things happen:

class TimeAndTemperature {
  const TimeAndTemperature({required this.time, required this.temperature});
  factory TimeAndTemperature.fromJson(Map<String, dynamic> json) => ...
  static final schema = ...

  final DateTime time;
  final double temperature;
}

final provider = Agent('google'), // or openai or anthropic or ...
  tools: [temperatureTool],
);

final result = await agent.sendFor<TimeAndTemperature>(
  'What is the time and temperature in Portland, OR?',
  outputSchema: TimeAndTemperature.schema,
  outputFromJson: TimeAndTemperature.fromJson,
);

print('time: ${result.output.time}');
print('temperature: ${result.output.temperature}');

I keep an eye out for provider improvements so as the LLMs get better, dartantic gets better, too.

Google Native JSON Schema: For example, Google’s Gemini API now uses native JSON Schema support via responseJsonSchema instead of the custom Schema object conversion. This is an internal change with no API surface changes for you, except that now you can pass in much more interesting JSON schemas - including anyOf, $ref, and other JSON Schema features that weren’t previously supported.

Quality of Life

I’ve also made some smaller improvements based on real-world user feedback. Keep those cards and letters coming!

Custom Headers

Real-world enterprise deployments often need to pass custom headers to API calls - for authentication proxies, request tracing, compliance logging, you name it. For those cases, dartantic 2.0 adds custom header:

final provider = GoogleProvider(
  apiKey: apiKey,
  headers: {
    'X-Request-ID': requestId,
    'X-Tenant-ID': tenantId,
  },
);

This has been plumbed through all of the providers: OpenAI, Google, Anthropic, Mistral, and Ollama. The headers flow through to all API calls, and custom headers can even override internal headers when needed.

Google Function Calling Mode

Also, in case you’d like to control just hard hard you push on Gemini using the tools you pass in, I added functionCallingMode and allowedFunctionNames properties to GoogleChatModelOptions:

final agent = Agent(
  'google',
  chatModelOptions: GoogleChatModelOptions(
    functionCallingMode: GoogleFunctionCallingMode.any, // Force tool calls
    allowedFunctionNames: ['get_weather'], // Limit to specific functions
  ),
  tools: ...
);

Available modes:

  • auto (default): Model decides when to call functions
  • any: Model always calls a function
  • none: Model never calls functions
  • validated: Like auto but validates calls with constrained decoding

Breaking Changes

I took this opportunity in the major version bump to break some things that have been bothering me.

Simplified Provider Lookup

I removed static provider instances, e.g. Providers.google, as being not useful in practice. Either you want the default initialization for a project and the convenience of using a model string, e.g. Agent('claude'), or you want to use the type and create a provider instance with non-defaults, e.g. OpenAIProvider('openai-responses:gpt-5', apiKey: ...). The halfway of having a typed default instance was good for discovery, but if you’re using syntax completion to choose your LLM, now you’ve got two problems. :)

// OLD
final provider = Providers.openai;

// NEW
final provider1 = OpenAIProvider();

Once I removed the static instances, there was no need for an entire type just to look up providers, so I moved that to Agent instead. Also, providers are now created via factory functions, not cached instances.

// OLD
final provider = Providers.get('openai');
final allProviders = Providers.all;
Providers.providerMap['custom'] = MyProvider();

// NEW
final provider = Agent.getProvider('openai');
final allProviders = Agent.allProviders;
Agent.providerFactories['custom'] = MyProvider.new;

Custom providers can be plugged into the new Agent.providersFactories map, so named-based lookup works just like built-in providers.

Removed ProviderCaps

I added ProviderCaps originally to help users drill in on what providers they could use in their apps. However, it really became “what are the capabilities of the default model of that provider” because every model on every provider is different and cannot be captured with one enum. It’s still useful for driving tests, so I moved it into the tests and took it out of the provider interface as misleading.

// OLD
final visionProviders = Providers.allWith({ProviderCaps.chatVision});

// NEW
// use Provider.listModels() and choose via ModelInfo instead

For runtime capability discovery, use Provider.listModels() instead - it gives you more accurate per-model information.

Removed Flakey Instrinsic Providers

There are lots and lots of OpenAI-compatible providers in the world, so trying to test Dartantic against all of them is impractical. Plus, most of them don’t do such a great job of actually implementing the features, e.g. multi-turn tool calling.

So, I’ve removed three of them from the list of built-in providers (Together, Google OpenAI-compat, and Ollama OpenAI-compat) and moved them to the openai_compat.dart example. You can still use them and define them in your app - in fact, they can be configured to work exactly like the built-in providers using the new Agent.providerFactories - but they’re not built in and they’re no longer part of the Dartantic testing suite.

I did leave the Open Router provider as built-in via Agent('openrouter') since it’s so popular and they do a good job of implementing the API across their models.

Exposing dartantic_interface from dartantic_ai

The dartantic_interface package is great for building your own providers without pulling in all of Dartantic. However, the way I had it split meant that you had to import both packages into every file that used them both. No more!

// OLD - had to import both packages
import 'package:dartantic_ai/dartantic_ai.dart';
import 'package:dartantic_interface/dartantic_interface.dart';

// NEW - one import does it all
import 'package:dartantic_ai/dartantic_ai.dart';

What’s Next?

I’m continuing to track the LLM provider landscape and add support for new features as they become available. I’ve certainly got plenty on my list to do. : )

If you run into issues or have feature requests, please open an issue on GitHub. And if you build something cool with Dartantic, let me know! I’d love to hear about it.

You can get the details here:

Enjoy!

Welcome to dartantic_ai 1.0! July 29, 2025 Flutter AI

Welcome to dartantic_ai 1.0!

Dartantic is an agentic framework designed to make building client and server-side apps in Dart with generative AI easier and more fun!

It works across providers (Google, OpenAI, Anthropic, etc) and runs anywhere your Dart code runs (Flutter desktop, Flutter mobile, Flutter web, CLI, server).

It allows you to write code like this:

// Tools that work together
final tools = [
  Tool(
    name: 'get_current_time',
    description: 'Get the current date and time',
    onCall: (_) async => {'result': DateTime.now().toIso8601String()},
  ),
  Tool(
    name: 'find_events',
    description: 'Find events for a date',
    inputSchema: JsonSchema.object({
      'date': JsonSchema.string(),
    }),
    onCall: (args) async => ..., // find events
  ),
];

// Agent chains tools automatically, no matter what provider you're using,
// e.g. openai, google, openrouter or your custom provider. And if you want to
// specify the model, you can, e.g. "openai:gpt-4o", "google:gemini-2.5-flash" or
// "your-provider:your-model".
final agent = Agent('openai', tools: tools);
final result = await agent.send('What events do I have today?');

// Agent will:
// 1. Call get_current_time to figure out what "today" means
// 2. Extract date from response
// 3. Call find_events with that date
// 4. Return final answer with events

I had all of that working with Gemini and OpenAI LLMs three weeks ago. I just needed to add support for a few more providers and I’d be ready for a 1.0. So I did what anyone would do: I spent three weeks rebuilding dartantic from first principles.

Building on langchain_dart

It was three weeks ago when I first really dove into the most excellent langchain_dart repo from David Miguel Lozano. And when I did, I discovered that he was way ahead of me with features AND providers. There was a lot of Langchain stuff in there of course — David had been very thorough — but it also had a lovely compatibility layer over the set of LLM provider-specific Dart SDK packages (which David also built and maintained). So, on the day after I launched dartantic 0.9.7 at FlutterCon in New York, I sat down with Claude Code and carved my way into David’s Langchain implementation, chipping away until I had extracted that compat-layer.

And on top of that, I built dartantic_ai 1.0.

As you can see from the most epic CHANGELOG ever, I learned a ton from David along the way, including:

  • to use Dart types for typed output on the Agent.sendFor<TOutput> method instead of on the Agent itself so each LLM response can have it’s own type
  • to use Dart types for typed input on tool calls on the parameterized Tool<TInput> type itself
  • to use a parameterized model options parameter so each model can be created in a generic way, but also support provider-specific typed model options
  • to expose a set of static provider instances, e.g. Providers.openai, Providers.anthropic, etc. to make it easy to just grab one without using string names if you don’t want to
  • to expose usage tracking
  • to handle embeddings in chunks
  • and so many other tiny details that just makes dartantic better!

David’s langchain base allowed me to build support for 11x providers, 5x native (Mistral, Anthropic, Google, OpenAI and Ollama) and 6x more OpenAI-compatible configurations (Together, Cohere and Lambda as well as Ollama and Google configurations for their OpenAI-compatible endpoints). All 11x providers handle chat and 5x of them handle embeddings. I started with more OpenAI-compatible configurations, but their implementations were either so weak or so flakey or so both (I’m looking at you, Nvidia) that I dropped them — they couldn’t pass the more than 1100 tests I built out to test dartantic’s support for them. But feel free to drop in your own!

Industrial Strength

On top of David’s langchain work, I then built out a lot of new features for dartantic, including:

  • custom providers that participate in the named lookup just like the built-in providers
  • typed output
  • typed tool input
  • typed output WITH tool calls WITH streaming (progressive JSON rendering anyone?)
  • multi-provider chat-compatible message format
  • thorough logging w/ easy setup and filtering
  • usage tracking
  • and more…

You can see the nitty gritty in the dartantic docs.

What’s Next

I’ve separated out the core dartantic interfaces so that you can build a dartantic provider without depending on all of dartantic and so that I can make sure that dartantic continues to run everywhere that Dart runs. I’m working with the nice folks at Cactus to get their enterprise-grade local mobile-device-optimized LLMs into dartantic as a custom provider. I also want to get a provider for firebase_ai in there for my Flutter peeps who don’t want to mess with API keys in their client apps.

Of course, anyone that wants to can build a dartantic provider. Let me know if you do! I’d love to track them in the docs.

I also have plans to support image generation and audio transcription, as well as the new OpenAI Responses API and context caching to reduce token usage.

And I have big dreams for a dartantic builder that translates Dart types into JSON serialization and JSON schema for you automatically, streamlining the agent creation considerably:

@Agent()
class TacAgent extends Agent {
  TacAgent(super.model);

  @Run()
  Future<TownAndCountry> run(String prompt) => _$TownAndCountryAgentRun(prompt);
  
  @Tool()
  Future<DateTime> getCurrentDateTime() => DateTime.now();
}

I’m tracking my ideas for the future of dartantic on GitHub. Feel free to add your own.

Where Are We

My goal with dartantic isn’t for me to be a one-man band. The idea is that dartantic can grow with the AI needs of the Dart and Flutter community, while maintaining its principles of multi-provider support, multi-platform support and fun!

Want to steer where dartantic goes? Hate something and want it fixed? Get involved! Here’s how:

If you’re building AI-powered apps in Dart or Flutter, give dartantic a try. Switch between providers. Use typed output. Make tool calls. Build agents. Break things. Swear at it. Then come tell me what went wrong.

Welcome to dartantic 1.0. Let’s go break some stuff together.

The 5 Stages of AI Grief July 22, 2025 AI

The 5 Stages of AI Grief

“The future is already here — it’s just not very evenly distributed.” –W. Gibson

As a consultant and speaker, I talk to a lot of software engineers. As AI coding tools have gotten better (and they have gotten much better), I’ve watched engineers move through what feels a lot like the stages of grief.

1. Denial: “AI is a fad. It’ll go away soon.”

denial

I still run into a large number of engineers who are convinced that AI coding is just hype that’ll blow over like so many other tech fads (Web 3, blockchain, NFTs, … they have a point). They refuse to even try ChatGPT, Copilot or Claude Code. They’ve been writing code the same way their whole lives and why should they change now?

2. Anger: “AI doesn’t work. I tried it two years ago and it sucked.”

anger

Some engineers have tried AI coding tools, but they tried them when they were genuinely pretty bad. GPT-3.5 in early 2023 was… let’s call it “inconsistent.” So they tried it, it failed to solve their problem, and they walked away convinced that AI coding was overhyped nonsense.

Or, these are the engineers who have strict company policies about which tools and which LLMs that they can and can’t use, often in-house, self-made stuff that leaves something to be desired. To be fair, these home-grown tools often do suck.

The problem is that these engineers haven’t (or aren’t allowed to) try the current crop of tools. They don’t realize that the AI that couldn’t write a for-loop eighteen months ago can now architect entire applications, if used correctly. But until they get over that hump, they’re not going to see the value in them.

3. Depression: Vibe coding: “Build me a healthcare app”

depression

This is the stage where engineers realize AI actually works, but they’re holding it wrong. They’re trying to go from zero to sixty in 3.5 seconds with prompts like “Build me a healthcare app” or “Fix this bug in my code.”

Vibe coding works great when you’re building something small and self-contained. But then you ship that healthcare app and get hacked with an SQL-injection attack because you’re not an engineer at all and you don’t know what SQL injection is. That’s when the depression sets in.

The tool isn’t the problem. The problem is treating AI like a magic wand instead of a chainsaw. The chainsaw will get the job done, but you’ve got to know what you’re doing or you’re just going to hurt yourself.

4. Bargaining: Describe coding: “Let’s design a new feature”

bargaining

I don’t do “vibe coding.” OK. Well. I have “experimented” with it. But I was younger. And I needed the money. And it was tastefully done!

Now, I’ve grown a bit and realize that there are better ways. I’ve adopted a technique I call “describe coding” (patent pending. all rights reserved. I do own the domain name : ). Instead of leaping right into “build me a thing that does a thing”, I start with “let’s think about this for a minute.” I like AI coding tools that have an explicit planning mode, but even without that mode I use prompts like “I’d like to design a … It should work like … It should have these constraints… ask any questions you may have before you start coding.” Actually, that last sentence I use so often, I’ve stored it in a snippet behind a hotkey on my Mac.

I collaborate on the AI until we come up with a design I like. Then the implementation. Then fixing the compiler errors (and the warnings, I’m not an animal!).

Then I dump each substantial feature into a design doc for future use. It will be useful in the future to get myself and the AI on the same page when it’s time for updates/bug fixes.

Then I generate tests and run them till they pass, being careful to really check that the tests model the behavior I want. Then update the docs and produce the PR.

Notice what I’m doing: design => implementation => testing => …

This is the standard practice that we’ve been doing for decades. You could call the use of my traditional software engineering techniques “bargaining” but I like to think of it as applying the techniques that really work, but in a new way.

The combo of AI + the application of software engineering is where the magic happens, letting me code in minutes or hours what used to take days or weeks. The AI becomes a super-fast pair programming partner instead of a glorified autocomplete.

Plus, it’s so much frickin’ fun, I can’t stand it! If you only get to this stage, you’ll do well with AI coding.

And there’s still one more stage to go!

5. Acceptance: Orchestrating agent swarms

acceptance

The engineers who’ve made it to acceptance aren’t just using AI to write code. They’re orchestrating whole sets of them. Personally, I like to keep about three projects going at once, switching between them, using different instances of my favorite AI coding agent of the week (things are changing really fast). Even keeping to just a few projects, I still find myself with the “oops wrong chat” problem, so that may be my limit.

Some people are pushing the limits, however, by combining AI agents at the command line with tmux and a little known feature of git called “worktrees,” which gives each agent instance its own playground.

Once you’re swarming, you’re not a software engineer anymore — now you’re an engineering manager with a team. Swarm mode is where your points really rack up.

1. Denial… Again: “Remote coding”

denial again!

Remote coding is giving AI agents in the cloud access to your repo and asking them to do things; they can create entire PRs without you ever seeing the code or the running app.

There is a growing set of AI coding products that provide for the “close your eyes and think of England” kind of remote asynchronous coding and it’s not OK with me!

And so the cycle begins again with denial.

The Questions We’re All Asking

When I discuss the advancement of AI into our day to day work with folks, some questions keep coming up:

Will using AI atrophy my knowledge? Some skills will almost certainly atrophy - that’s what happens to muscles that aren’t used. But we lost our tails because we never used them either. If something dries up and falls off due to misuse, how important was it in the first place?

Will AI take my job? I honestly don’t know. But I do know this: software engineers who use AI tooling are going to be more effective and efficient than those who don’t. And when promotion time comes around, or when layoffs happen, effectiveness and efficiency are good qualities to have.

Will AI produce more, different jobs? Every single technology we’ve ever invented has put someone out of work. When Grog the plump caveman lost his cuddling-to-keep-the-tribe-warm job after fire was invented, his extra berries at bedtime were gone.

I don’t know what happened to Grog, but I can tell you that the invention of fire led to pretty much every other job. Should we avoid a new technology because it points to an uncertain future?

Every new technology seems different - this one only destroys jobs and doesn’t create them - because the lost jobs happen first and we can’t see into the future. The Luddites broke into fabric mills and destroyed steam-powered looms because they didn’t want to lose their jobs. Of course, we ended up creating many more jobs with the machines that looms ultimately led to than the looms ever created on their own.

Is AI going to be different? Is it only going to destroy jobs and not create them? I don’t know. But if that were the case, it would be unique in human history.

Where Are We?

All technology advances happen faster now. The spread of electricity took ~45 years to reach 25% of the US population. The internet took ~7 years. AI has been making changes in our society as large as those other two in just 2.5 years. What that means for us puny humans, I don’t know.

But here’s what I do know: the grief you’re experiencing with the oncoming AI is real. We are losing things. We’re already losing knowledge and skills. Artists and other content creators seem to have lost their IP. The new people entering every field that uses AI are going to do things differently; the old ways will be lost.

The question isn’t whether we’re going to lose things with AI. The question is: is what we gain going to be worth it? Will it be a higher standard of living for our children? Will AI help us solve real-world problems that we’ve been unable to solve ourselves? Once we get over the grief, will we be able to experience joy in the new world that we’ve created for ourselves?

I hope so.

The engineers who are curious, who are experimenting, who are moving through these stages thoughtfully - I believe that they’ll do just fine in whatever future we create for ourselves. The ones who get permanently stuck in anger or denial? I think they’ll have a harder time.

The future is already here. What are you going to do about it?

A Young Software Engineer’s Guide to AI July 16, 2025 AI

A Young Software Engineer’s Guide to AI

I was on an AI-focused podcast last week talking about how a new software engineer should work differently in this new era of AI. It reminded me of a conversation I had recently with a college grad in their first professional software engineering career. They were asking for advice from a wizened old coder (I was even wearing the suspenders). With the latest in AI coding tools, they were productive for sure, but they didn’t understand all of the code that the AI agent was producing. They were afraid that without being forced to write the code they old-fashioned way for cough 40 years cough, that they weren’t ever really going to understand what they were doing.

I don’t think that they are alone.

With that in mind, I’ve composed a letter for new SWEs just getting started with their careers.

Dear New Software Engineer

Congratulations on landing your first job! I know it’s exciting and terrifying at the same time. You’re probably sitting in an open-plan office (sorry about that), watching veterans write code with instincts honed through years of hands-on experience. Watching them work, you’re probably wondering how you’ll develop that same intuition when the latest corporate mandates encourage you to use AI coding agents. Especially when those agents generate code you don’t understand.

That’s OK. You’re not expected to understand all of the code you see at first, no matter who (or what) wrote it.

But that doesn’t mean you get to shrug your shoulders and press the commit button.

You’re an engineer: it’s your job to stand behind every line of code that you submit.

If you don’t understand what the AI is suggesting, then it’s your job to learn, even if you no longer have to write that code yourself. The good news is you’re in a better position to develop coding instincts than any generation of software engineers before you.

How We Old-Timers Learned

Back in my day, we walked uphill both ways to compile our code. And we were happy!

It was a different time and we used different techniques. We spent countless hours reading other people’s code - in books like Steve McConnell’s Code Complete, in discussion groups, on mailing lists. We debugged other people’s mistakes. We made our own mistakes. We’d argue about design patterns in Friday lunch-and-learns and spend weekends diving into open source projects just to understand how they worked.

The process was slow, sometimes tedious, but it built something invaluable: coding instincts. The ability to look at a piece of code and know “that’s just wrong” even before you can articulate why. Having an opinion about what’s okay and what’s not OK in your code. Everyone develops their own instincts, but once you have them, you can spot problems that would take someone else hours to debug.

Learn the Same Way, But Faster

Those same learning techniques still work today. In fact, they work better than ever because you have an all-day, every-day collaboration partner who never gets tired of your questions (sorry, Mike, I know you had other work to do…).

You don’t have to wait for Friday’s lunch-and-learn to discuss the code you read about in Jon Bentley’s Programming Pearls. You can ask your AI to explain itself to you right now. When you see code you don’t understand, ask questions:

  • Why did you choose that approach?
  • What other options were available?
  • Is that the right solution for this specific problem?
  • What are the trade-offs of this approach?
  • Can you show me an alternative way to solve this?
  • What happens if [edge case] occurs?
  • Can you walk through this algorithm step by step?

Here’s a conversation I had recently with my AI-coding-agent-of-the-week:

Me: We (well, you really) just implemented simple hierarchical logging using a naming scheme, e.g. Logger(‘dartantic.chat.models’). I understand that the Dart logging package has a “hierarchical logging feature built in. How does that differ from ours and should we be using that instead?

AI: I’ll take a look…

…looks it up…

AI: “Here’s some sample code for using the hierarchical logging feature in the logging package:

…ugly, complicated hierarchical detail control code…

What you’ve done in this library is simpler and fits the needs of the library better. Let’s keep using what you’ve already done.”

Me: Thanks. I agree.

I learned about a feature I didn’t know existed, saw how it worked and then decided not to use it. That’s exactly the kind of exploration we’d do in the olden days of yore but now it happens in minutes or hours instead of days or weeks.

Go Further

But you don’t have to stop at learning the way we old-timers; you can go beyond:

  • Explore architectural patterns we never had time to try
  • Experiment with different approaches in minutes instead of days
  • Get instant feedback on code quality and best practices
  • Build prototypes to test ideas that would have taken weeks to implement
  • Write the spec, generate the code, throw away the code, update the spec, generate the code again, etc.

You’re not just getting help from an AI coder. You’re getting help from an AI coder trained on the collective knowledge of every software engineer who ever lived.

The patterns that took years to discover, the insights that made industry legends famous, the hard-won wisdom from decades of production systems - it’s all there. You just have to ask.

Coding Instincts - An Example

As you do this more, something interesting happens. You start developing opinions about the code you’re seeing. When something feels wrong, you know it, even if you can’t immediately explain why.

That’s when conversations like this start happening:

AI: I see the problem. It’s a bug in the underlying library. I’ll write a workaround.

…Me hitting the stop button…

Me: I’m sorry. I don’t believe you. Are you saying that we’ve just discovered a new bug in the underlying library that happens to coincide with the new code we just wrote? That’s as unlikely as getting hit by lightning while winning the lottery. I’d like you to write some diagnostic code to validate that claim before committing to a workaround, please.

…writing and running some diagnostic code…

AI: You’re right! The problem is in our code…

That’s what coding instincts look like. And it’s that gut feeling that you’re developing every time you ask the AI to explain itself, every time you ask for alternatives, every time you push back on its suggestions.

Don’t just accept what the AI gives you. Ask it to write tests for the code it created. Ask it to add diagnostic output to validate its assumptions. Ask it to critique its own solution.

Every time you do this, you’re doing the same thing we did when we spent hours in design review meetings or practiced test-driven development. You’re just doing it faster, with more patience from your “mentor,” and with access to more knowledge than any of us ever had.

Keep Asking Why

I know you feel pressure to be immediately productive, to understand everything right away. Don’t get caught up in that. Every software engineer is constantly learning. Even after 40 years of doing things the hard way, I still learn things from AI every day.

If you stay curious and engaged, your coding instincts will develop just fine. In fact, they’ll probably develop faster and be more robust than mine ever were.

Yours sincerely, Chris Sells

P.S. Keep a close eye on AI coders that wrap errors in exception handling in the name of “defensive coding” but really just to get the tests passing. They’re sneaky that way…

Flutter AI Tool Calling May 28, 2025 Flutter AI

Flutter AI Tool Calling

A little while ago, I was inspired by Thorsten’s blog post on building an AI Agent using Rust to build an AI Agent using Dart. The combination of a conversation with Gemini and a set of tools allowed us to build an agent that could take some prompts from the user and turn them into not just responses (Ask mode), but actions (Agent mode!). In the spirit of Agentic Apps month for Flutter this month, I wanted to share how to do the same thing in your Flutter app using the most recent release of the Flutter AI Toolkit.

Flutter AI Toolkit v0.9.0

As we near the 1.0 release of the AI Toolkit, the community has continued to contribute features that they’d like to see in a customizable, style-able and LLM-pluggable widget you can use when you’d like to enable your users to be able to talk to an AI in the context of your app.

In this case, Toshi Ossada contributed a PR that provided the inspiration for tool calling for the new FirebaseProvider in the AI Toolkit. This new provider replaces both the GeminiProvider and the VertexProvider as described in the migration guide for v0.9.0.

Tool calling is the ability to augment an LLM with a set of functions — what the AI industry refers to as “tools” — that the LLM can call when it needs the data that the tools provide. For example, an LLM by itself has no idea what time it is; it needs to have some tool that can provide that information and if it doesn’t have one, it’ll just make something up. With confidence.

Here’s an example of how to provide tools to the FirebaseProvider:

class ChatPage extends StatelessWidget {
  const ChatPage({super.key});

  @override
  Widget build(BuildContext context) => Scaffold(
    appBar: AppBar(title: const Text(App.title)),
    body: LlmChatView(
      provider: FirebaseProvider(
        model: FirebaseAI.googleAI().generativeModel(
          model: 'gemini-2.0-flash',
          tools: [
            Tool.functionDeclarations([
              FunctionDeclaration(
                'get_temperature',
                'Get the current local temperature',
                parameters: {},
              ),
              FunctionDeclaration(
                'get_time',
                'Get the current local time',
                parameters: {},
              ),
            ]),
          ],
        ),
        onFunctionCall: _onFunctionCall,
      ),
    ),
  );
  
  ... // _onFunctionCall goes here...
}

This code initializes the model with two tools: get_temperature and get_time. These tools come with names and descriptions so that the model can understand what they’re for and make an informed decision about when to call them.

The model is also initialized with an onFunctionCall callback so that when the LLM wants to use one of those tools, your function is called to handle it:

class ChatPage extends StatelessWidget {
  ...

  // note: we're not actually calling any external APIs in this example
  Future<Map<String, Object?>?> _onFunctionCall(
    FunctionCall functionCall,
  ) async => switch (functionCall.name) {
    'get_temperature' => {'temperature': 60, 'unit': 'F'},
    'get_time' => {'time': DateTime(1970, 1, 1).toIso8601String()},
    _ => throw Exception('Unknown function call: ${functionCall.name}'),
  };
}

We’re just returning hard-coded values here, but this is the place where you’d look up the data that the LLM wants as part of fulfilling the user’s request, as shown here:
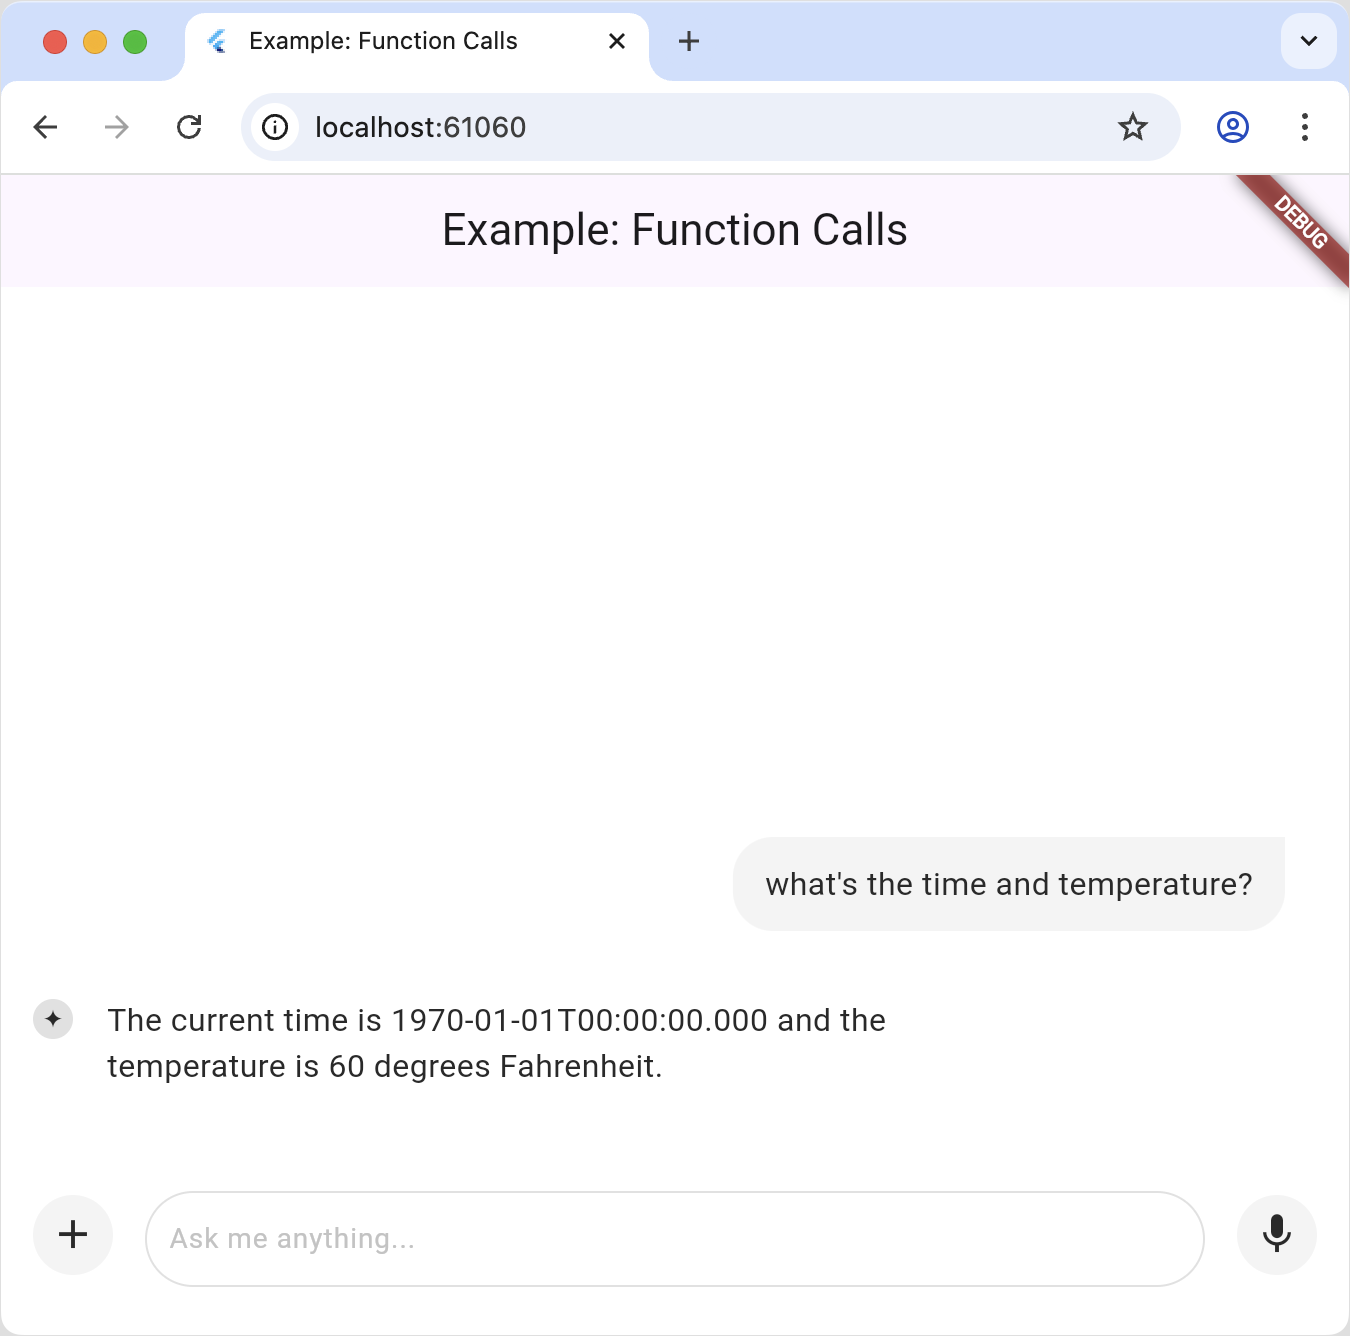
In this example, we’re just looking up information that the LLM would have trouble getting on it’s own. However, if a call to a tool has a side affect then BOOM you’ve moved from Ask mode to Agent mode. Welcome to the future!

Flutter + Genkit + Interrupts (oh my!)

This all works great so long as everything is handled on the client-side. However, as soon as you mix in server-side LLMs, for example by using Genkit, you have some additional considerations to take into account.

Genkit is an open-source framework for building full-stack AI-powered applications, developed and used in production by Google. It currently has language support for Typescript/Javascript, Go and Python but unfortunately not Dart. However, if you’re willing to write some Typescript, it turns out that Genkit has great support server-side tools handled by Flutter apps with something called interrupts.

A Genkit interrupt is a tool that’s invoked on the server but fulfilled on the client.

“How can that work?” I’m hearing you ask through the Interwebtubes.

Well let me tell you.

The way an LLM tool works is that during the handling of a request, if there’s a tool involved, the LLM API will call back into the function you provided via a callback like onFunctionCall . That call might take a while, e.g. you may need to dial up the national weather service, but when, the Future will complete and the LLM will be able to carry on.

“That’s great,” you say. “But how do I stretch a function callback over the wire from a Genkit server to a Flutter client?” You ask such good questions.

Well, as it turns out, tool calls being invoked in the middle of an LLM response is an API fiction. What’s really happening is that when an LLM wants to call a tool, it replies with a message marked as a tool call and that include the tool arguments. The LLM client library — like the firebase_ai package — notices this, calls your callback function, bundles up the response and continues the conversation without bothering you about it at all until the actual LLM response comes back, having taken into account the results of the tool call(s).

For example, the user’s request above in a single prompt looks like it returns a single response, but looking at the actual message history tells a different story:

[
  {
    "role": "user",
    "parts": [
      {
        "text": "what's the time and temperature?"
      }
    ]
  },
  {
    "role": "model",
    "parts": [
      {
        "functionCall": {
          "name": "get_time",
          "args": {}
        }
      },
      {
        "functionCall": {
          "name": "get_temperature",
          "args": {}
        }
      }
    ]
  },
  {
    "role": "function",
    "parts": [
      {
        "functionResponse": {
          "name": "get_time",
          "response": {
            "time": "1970-01-01T00:00:00.000"
          }
        }
      },
      {
        "functionResponse": {
          "name": "get_temperature",
          "response": {
            "temperature": 60,
            "unit": "F"
          }
        }
      }
    ]
  },
  {
    "role": "model",
    "parts": [
      {
        "text": "OK. The current time is 1970-01-01T00:00:00.000 and the temperature is 60 degrees Fahrenheit."
      }
    ]
  }
]

“OK,” you say warming up to another question, “but what’s that got to do with Genkit and server-side tool calls?” I’m getting there!

Genkit Tools

Genkit also provides for tool calls, as shown in this example:

// define a tool
const getWeather = ai.defineTool(
  {
    name: 'getWeather',
    description: 'Gets the current weather in a given location',
    inputSchema: z.object({
      location: z.string().describe('The location to get the current weather for'),
    }),
    outputSchema: z.string(),
  },
  async (input) => {
    // Here, we would typically make an API call or database query. For this
    // example, we just return a fixed value.
    return `The current weather in ${input.location} is 63°F and sunny.`;
  },
);

// use a tool
const response = await ai.generate({
  prompt: "What is the weather in Baltimore?",
  tools: [getWeather],
});

This is semantically the same — we define a tool that the LLM can call during a request. And again, it looks like a seamless callback, which you need to implement on the server, even though we know there is a flow of messages underneath just like what we see above.

But what if you could interrupt the flow of messages when there’s a tool call, pass the stack of messages back to the Flutter app and let it fill in the results? That’s exactly what Genkit interrupts are for.

Genkit Interrupts: Human in the Loop

From the Genkit docs: “Interrupts are a special kind of tool that can pause the LLM generation-and-tool-calling loop to return control back to you. When you’re ready, you can then resume generation by sending replies that the LLM processes for further generation.”

As an example, imagine that you’ve got an app that helps people with their plants, maybe expanding their garden or diagnosing their sick plants.
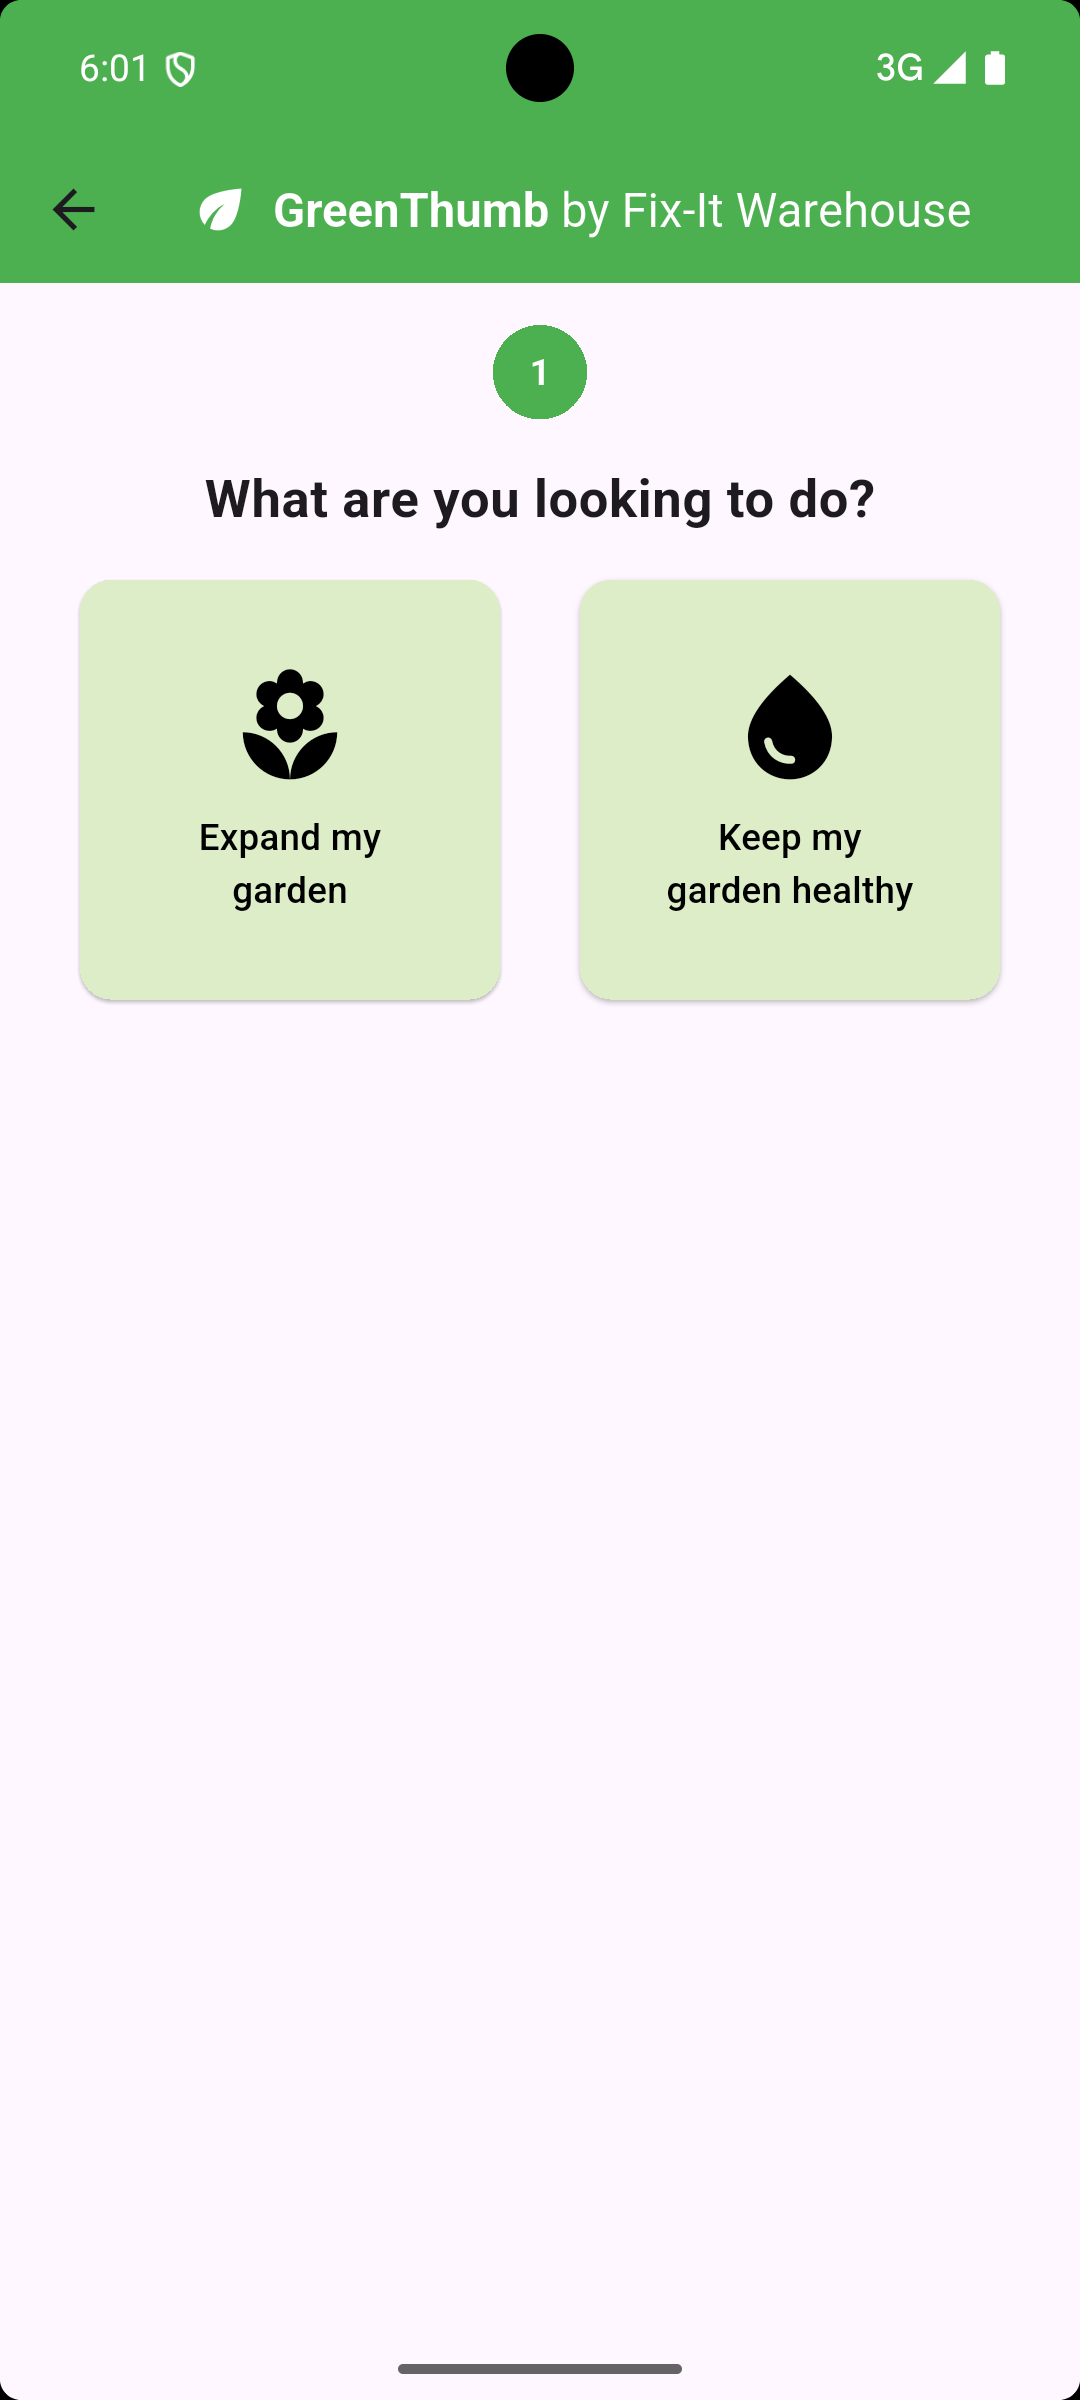
Further imagine that you’ve got an LLM in your server-side code with access to a database of products that can help users with their plant needs.
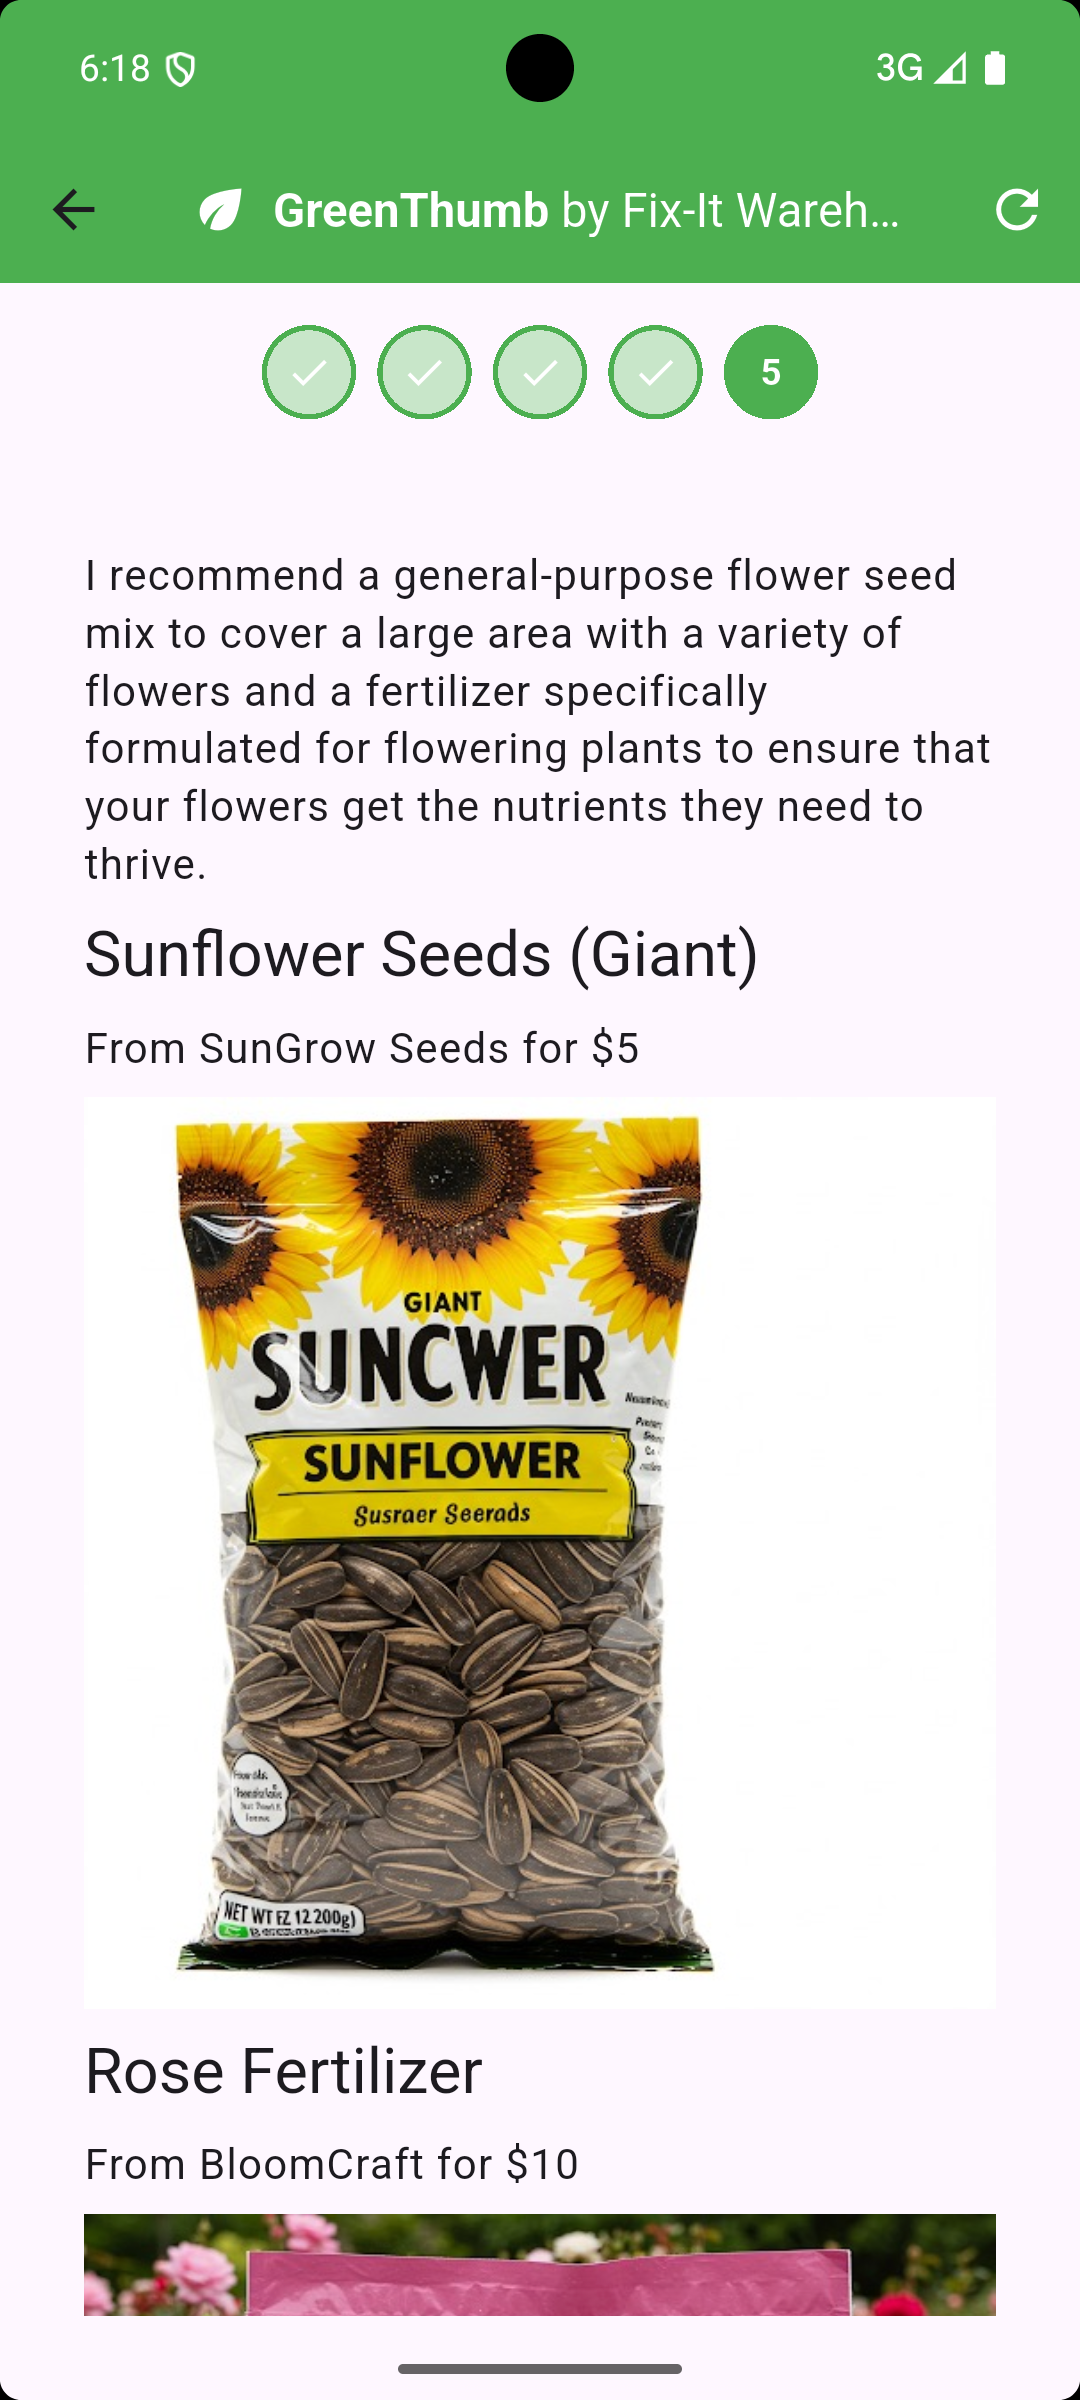
Now imagine that the LLM has been instructed to ask the user a set of questions to clarify the plant needs before recommending one of those products.
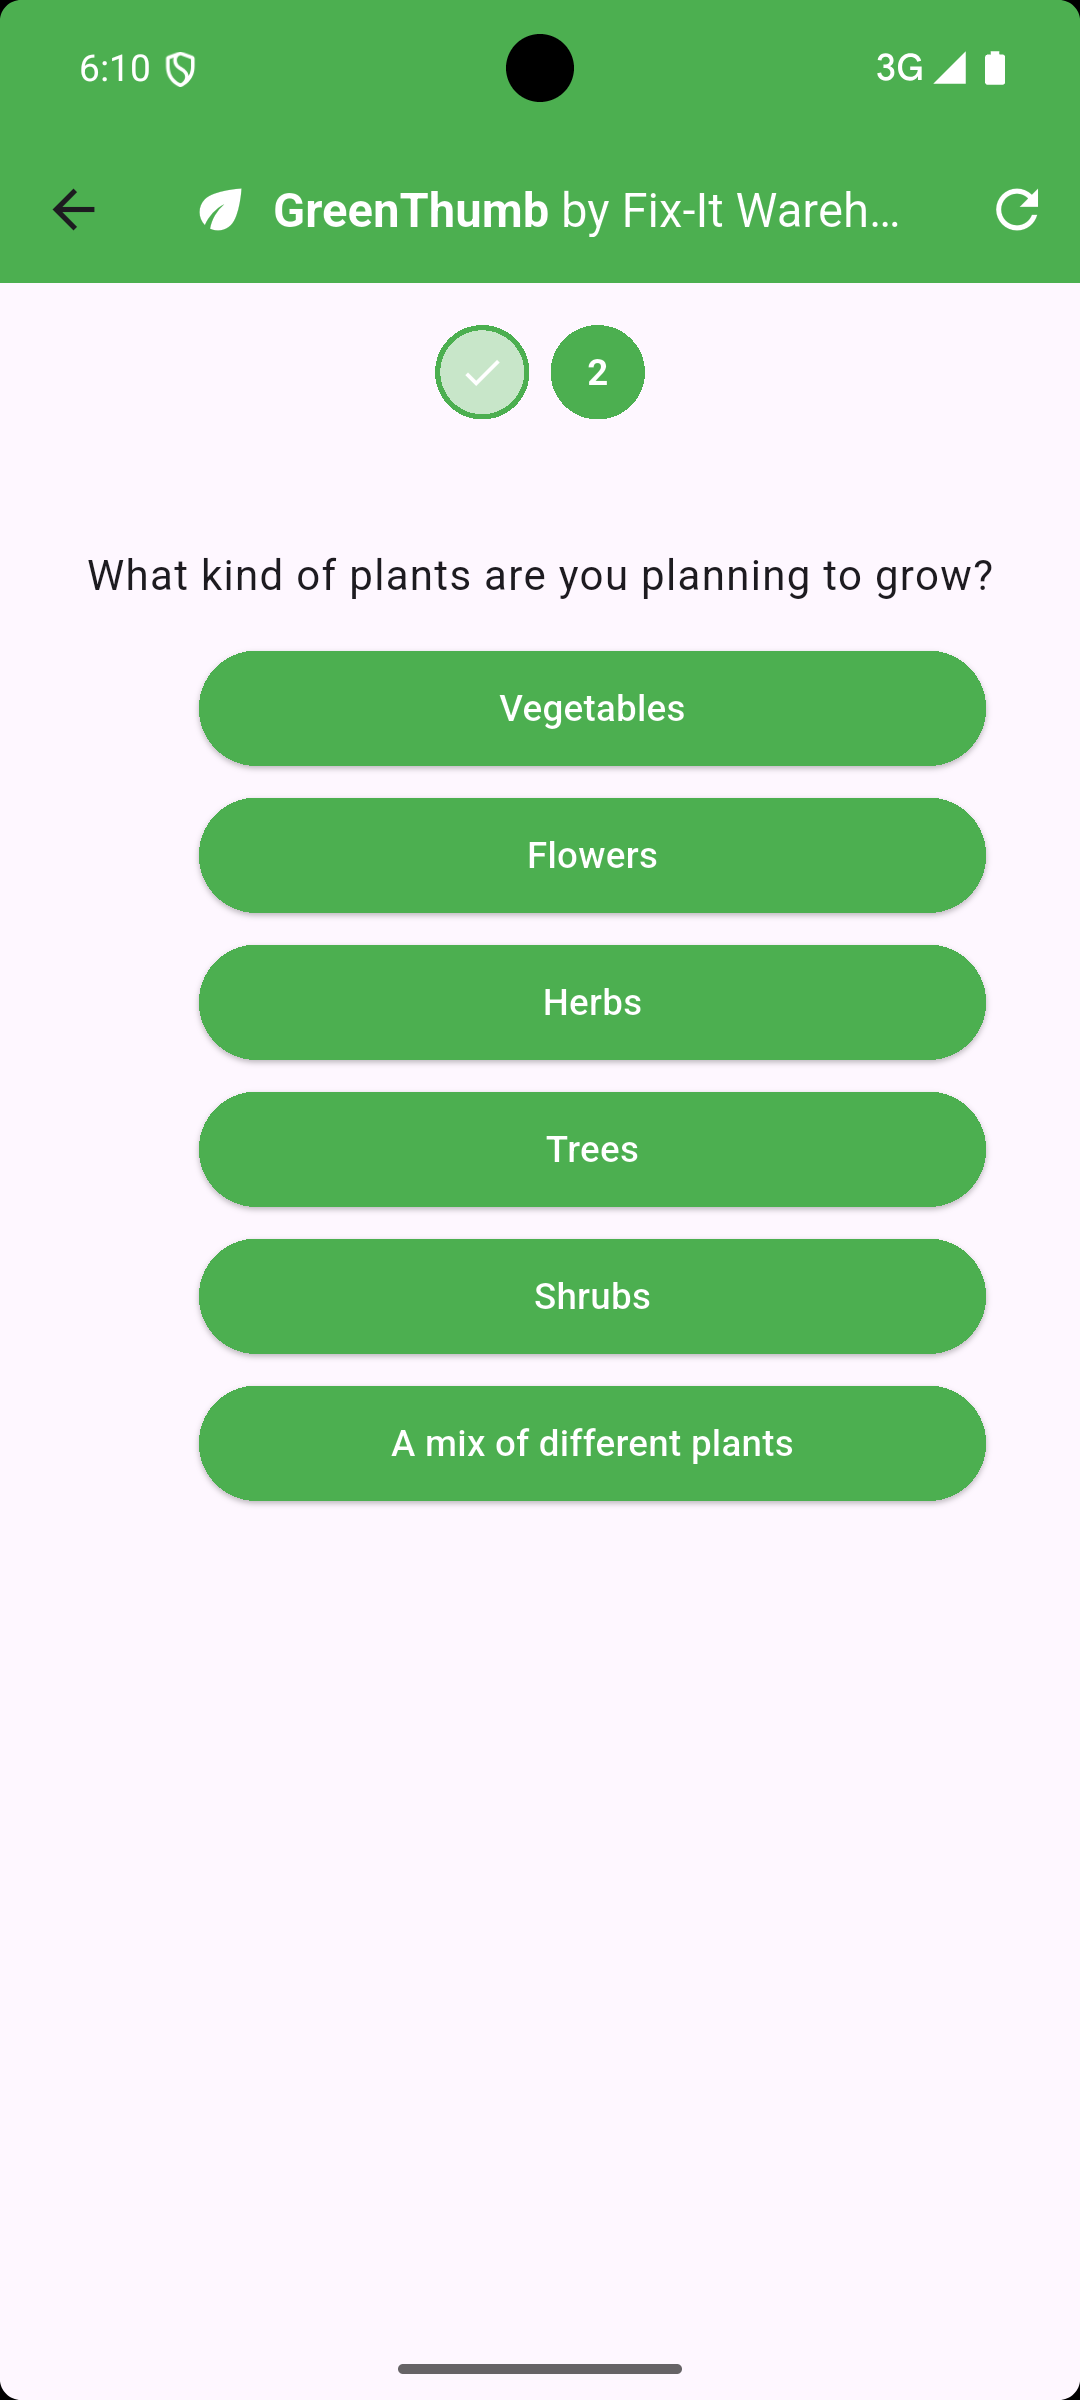
Since the LLM is running in your Genkit server with access to your server-side database of products, to involve the user of your Flutter app in a conversation, you’ve now got the perfect storm for using interrupts to keep the “human in the loop.”

To implement this in Genkit, you define your tools as interrupts so that the LLM can pause the response to gather data from the user:

const choiceInterrupt = ai.defineInterrupt(
  {
    name: 'choice',
    description: 'Asks the user a question with a list of choices',
    inputSchema: z.object({
      question: z.string().describe("The model's follow-up question."),
      choices: z.array(z.string()).describe("The list of choices."),
    }),
    outputSchema: z.string().describe("The user's choice."),
  });

In Genkit, an endpoint that you can call from your Flutter app via HTTP is called a “flow”:

const greenThumb = ai.defineFlow(
  {
    name: "greenThumb",
    ...
  },
  async ({ prompt, messages, resume }) => {
    const response = await ai.generate({
      ...(messages && messages.length > 0 ? {} : { system: gtSystem }),
      prompt,
      tools: [choiceInterrupt, ...],
      messages,
      resume,
    });

    return { messages: response.messages };
  });

Notice that the greenThumb flow takes a set of messages and returns a set of messages. To kick things off in your Flutter code, you pass an empty list of messages. If the last message in the LLM response is an interrupt, it will include the info you need to show a UI to ask the user to answer the LLM’s question:

{
  "messages": [
    {
      "role": "system",
      "content": [
        {
          "text": "\n  You're an expert gardener. The user will ask a question about how to manage\n  their plants in their garden. Be helpful and ask 3 to 5 clarifying questions,\n  using the choiceInterrupt tool.\n  \n  When you're done asking questions, provide a description of a product or\n  products that will help the user with their original query. Each product\n  description should NOT include another question for the user nor should it\n  include the name of any specific product.\n"
        }
      ]
    },
    {
      "role": "user",
      "content": [
        {
          "text": "I'd like to expand my garden."
        }
      ]
    },
    {
      "role": "model",
      "content": [
        {
          "text": "That's great! To give you the best advice, I need a little more information.\n\n1.  What kind of plants are you planning to add to your garden (e.g., vegetables, flowers, shrubs)?\n2.  What is the approximate size of the area you're planning to expand?\n3.  What type of soil do you have in your garden currently (e.g., sandy, clay, loamy)?\n4.  What is the average amount of sunlight your garden receives each day?\n\n"
        },
        {
          "toolRequest": {
            "name": "choiceInterrupt",
            "input": {
              "choices": [
                "Vegetables",
                "Flowers",
                "Shrubs",
                "Other"
              ],
              "question": "What kind of plants are you planning to add to your garden?"
            }
          },
          "metadata": {
            "interrupt": true
          }
        }
      ]
    }
  ]
}

This continues until the LLM gathers the data it needs to provide a response:

{
  "messages": [
    ...
    {
      "role": "model",
      "content": [
        {
          "text": "Based on your answers, here are a couple of product descriptions that might be helpful for expanding your flower garden:\n\n**Product 1:** This soil amendment is designed to improve drainage and aeration in existing soil, while also providing essential nutrients for healthy root development. It's perfect for preparing new garden beds or revitalizing existing ones. Simply mix it into the top layer of soil before planting to create an ideal environment for flowers to thrive.\n\n**Product 2:** These granular plant food spikes provide a slow-release source of nutrients for flowering plants. They are easy to use - simply insert them into the soil around your existing plants, and they will gradually release nutrients over an extended period, promoting vibrant blooms and strong growth. They're especially beneficial for areas with full sun exposure, as they help plants maintain consistent access to the resources they need.\n"
        }
      ]
    }
  ]
}

Of course, there are a lot of picky details to get this right, so I’ll refer you my flutter_fixit_warehouse sample, which provides all of the code and a more thorough explanation.

Where are we?

With the latest updates to the Flutter AI Toolkit, you can now build tool calls into your Flutter agentic apps. Furthermore, with Genkit’s support for interrupts, you can keep the human in the loop by handling server-side tool calls with input from your Flutter app users.

Now, with these new tools in your toolbox, go forth and build!
Pedantic AI in Dart: dartantic_ai May 6, 2025 Flutter AI

Pedantic AI in Dart: dartantic_ai

The Python community has a library called pydantic that adds type checking at run-time to a dynamically typed language. The library allows them to be “pedantic” about type validation in Python aka pydantic; get it? : )

We don’t need that for Dart. We have static type checking and it’s wonderful.

Pedantic AI in Python: pydantic-ai

On top of pydantic, the Python community has built pydantic-ai, which makes it easy for you to specify typed output from your LLM requests and to describe typed access to your tools. For example:

# Python example with support for multiple models
import os

from pydantic import BaseModel
from pydantic_ai import Agent

class TownAndCountry(BaseModel):
    town: str
    country: str

model = 'openai:gpt-4o' # or 'google-gla:gemini-2.0-flash' or ...
print(f'Using model: {model}')
agent = Agent(model, output_type=TownAndCountry)

if __name__ == '__main__':
    result = await agent.run('The windy city in the US of A.')
    print(result.output) // Output: town='Chicago' country='United States'

Check out the definition of the TownAndCountry type and the use of it when creating an Agent object with the output_type parameter. That’s all you need to get an instance of TownAndCountry populated by the LLM based on the prompt.

Now that’s something we don’t have in Dart! Instead, we have to do something like this:

// Dart example for Gemini only
void main() async {
  final model = gemini.GenerativeModel(
    apiKey: Platform.environment['GEMINI_API_KEY']!,
    model: 'gemini-2.0-flash',
    generationConfig: gemini.GenerationConfig(
      responseMimeType: 'application/json',
      responseSchema: gemini.Schema.object(
        properties: {
          'town': gemini.Schema.string(),
          'country': gemini.Schema.string(),
        },
        requiredProperties: ['town', 'country'],
      ),
    ),
  );

  final result = await model.generateContent([
    gemini.Content.text('The windy city of the US of A.'),
  ]);

  final json = jsonDecode(result.text!);
  final obj = TownAndCountry.fromJson(json);
  print(obj); // Output: TownAndCountry(town: Chicago, country: United States)
}

Plus, while the above code works for the Gemini SDK for Dart, if I want to do the same thing using the OpenAI SDK for Dart, I have to write very different code:

// Dart example for OpenAI only
void main() async {
  final client = openai.OpenAIClient(
    apiKey: Platform.environment['OPENAI_API_KEY'],
  );

  final response = await client.createChatCompletion(
    request: const openai.CreateChatCompletionRequest(
      model: openai.ChatCompletionModel.modelId('gpt-4o'),
      responseFormat: openai.ResponseFormat.jsonObject(),
      messages: [
        openai.ChatCompletionMessage.system(
          content:
              'Respond ONLY with JSON containing keys "town" and "country".',
        ),
        openai.ChatCompletionMessage.user(
          content: openai.ChatCompletionUserMessageContent.string(
            'The windy city of the US of A.',
          ),
        ),
      ],
    ),
  );

  final data =
      jsonDecode(response.choices.first.message.content!)
          as Map<String, dynamic>;

  final result = TownAndCountry.fromJson(data);
  print(result); // Output: TownAndCountry(town: Chicago, country: United States)
}

There must be a better way!

A Better Way: dartantic_ai

I was inspired by pydantic-ai for two main features:

  1. An easy way to go between models using just a string descriptor, e.g. openai:gpt-4o
  2. A common way to provide type information for output and tool calls, i.e. JSON schema

Those are the features I focused on initially for dartantic_ai, allowing you to write code like the following:

// Dart example with support for multiple models
class TownAndCountry {
  TownAndCountry({required this.town, required this.country});
  final String town;
  final String country;  
  
  factory TownAndCountry.fromJson(Map<String, dynamic> json) => TownAndCountry(
      town: json['town'],
      country: json['country'],
    );
  
  static Map<String, dynamic> get schemaMap => {
    'type': 'object',
    'properties': {
      'town': {'type': 'string'},
      'country': {'type': 'string'},
    },
    'required': ['town', 'country'],
    'additionalProperties': false,
  };
  
  @override
  String toString() => 'TownAndCountry(town: $town, country: $country)';
}

void main() async {
  final agent = Agent(
    model: 'openai:gpt-4o', // or 'google:gemini-2.0-flash' or ...
    outputType: TownAndCountry.schemaMap,
  );

  final result = await agent.run('The windy city in the US of A.');
  final obj = TownAndCountry.fromJson(jsonDecode(result.output));
  print(obj); // Output: TownAndCountry(town: Chicago, country: United States)
}

Here we’ve created a class to hold the typed output from the agent, passing in hand-written JSON schema and JSON decoder functions. Already, this is much simpler code than either of the Gemini or the OpenAI samples and it works either family of models by simply changing the model description string.

Further, with a little bit of Dart builder magic, you can use json_serializable and soti_schema to generate the JSON serialization and JSON schema for you:

// Automatic JSON decoding and schema generation
@SotiSchema()
@JsonSerializable()
class TownAndCountry {
  TownAndCountry({required this.town, required this.country});

  factory TownAndCountry.fromJson(Map<String, dynamic> json) =>
      _$TownAndCountryFromJson(json);

  final String town;
  final String country;

  Map<String, dynamic> toJson() => _$TownAndCountryToJson(this);

  @jsonSchema
  static Map<String, dynamic> get schemaMap => _$TownAndCountrySchemaMap;

  @override
  String toString() => 'TownAndCountry(town: $town, country: $country)';
}

void main() async {
  final agent = Agent(
    model: 'openai:gpt-4o'
    outputType: TownAndCountry.schemaMap,
    outputFromJson: TownAndCountry.fromJson,
  );

  final result = await agent.runFor<TownAndCountry>(
    'The windy city in the US of A.',
  );

  print(result.output); // Output: TownAndCountry(town: Chicago, country: United States)
}

Using the builder, we no longer have to write the JSON serialization code or the JSON schema by hand — json_serialization and soti_schema handle that. And, for fun, we’re calling the runFor<T> method so that the output you get is typed w/o you having to manually call jsonDecode. Magic!

Potential Future

Right now, we’re in “phrase 1” of dartantic_ai development — building out the core set of features and providers that work with those features (starting with Gemini and OpenAI). That’s what the code samples above are all about — what’s the best developer experience we can provide for a working Dart developer adding generative AI to their apps?

Once there’s a solid foundation, we can start experimenting with a builder that would allow you to write even simpler code:

@Agent()
class TacAgent extends Agent {
  TacAgent(super.model);

  @Run()
  Future<TownAndCountry> run(String prompt) => _$TownAndCountryAgentRun(prompt);
}

void main() async {
  final result = await TacAgent('openai:gpt-4o').run('The windy city of the US of A.');
  print(result.output); // Output: TownAndCountry(town: Chicago, country: United States)
}

And this is just the beginning. Today, dartantic supports tool calls, which you define with JSON schema in a way that’s similar to typed output from a run call. Now imagine being able to put a @Tool attribute on a method in your agent class and have the tool passed in automatically for you. There are all kinds of possibilities as soon as builders are involved.

Call for Contributors

As of the writing of this post, I’ve just started my dartantic_ai journey with a list of current and pending features you can read about on pub.dev. I only support the smallest amount of the Gemini and OpenAI SDK surface area to implement the initial features that are most important to me.

However, pydantic-ai has a big surface area with lots of great stuff for using LLMs in a type-safe, multi-model way that the Dart community would be interested in, including multi-agent support, agent graphs, multi-media support, streaming, etc. I’m going to need help to cover all of that, let alone making it work in a robust, matrix-tested way that can appeal to a growing community of Dart developers dipping their toes into AI.

Is dartantic_ai a style of interacting with LLMs from Dart that appeals to you? Are there features missing that you want or bugs you’ve found putting it to use? Then have I got a deal for you! Please contribute issues and PRs and let’s get this show on the road!


Older Entries →